Readability plays an important role in creating useful SEO content. Search engines may bring visitors to your page. However, readers still need clear and helpful information. If your content feels difficult to read, visitors may leave quickly. Therefore, SEO writers should focus on both search visibility and user experience. Sentence structure, paragraph length, word choice, and content flow all affect readability. By improving these areas, you can create content that feels natural and easier to follow.
What Makes SEO Content Readable?
Readable SEO content communicates information without making readers work too hard. Therefore, start with simple and familiar language. Choose words that match your audience and topic. Keep each paragraph focused on one main idea. This approach helps readers follow your argument without losing context. It also makes longer articles easier to scan. Next, avoid unnecessary jargon whenever possible. Industry terms can help in some situations. However, excessive technical language can make your content feel complicated.
Finally, review your content from the reader’s perspective. Ask whether each sentence adds useful information. If a sentence feels unnecessary, consider removing or rewriting it.
Why Readability Matters for SEO Content
Readable content helps visitors understand information more quickly. As a result, readers can find answers without struggling through complicated sentences or dense paragraphs. Clear writing also improves the overall experience on your website. Visitors can scan headings, paragraphs, and lists more easily. They can then identify the information that matters most to them.
Moreover, readability encourages you to focus on the reader. SEO content should answer questions and provide useful information. It should not simply repeat keywords to target search engines. Keywords still have an important role in SEO. However, you should place them naturally within useful content. Forced keyword usage can interrupt the reading experience.
For this reason, treat readability as part of your content quality process. First, create useful information that matches search intent. Then, edit your writing for clarity and flow. A readable article can also make complex subjects easier to explain. Short sentences can clarify important points. Clear headings can guide readers through the topic. Together, these elements create a smoother reading experience.
How Readability Affects the Quality of SEO Content
1. Keep Sentence Length Under Control:
Long sentences can make SEO content harder to follow. They often contain several ideas that readers must process together. Therefore, break complicated thoughts into shorter sentences. A mix of short and medium-length sentences also creates natural flow. Avoid making every sentence too brief. Otherwise, your writing may sound repetitive.
An online sentence counter tool can help you review sentence structure. Simply paste your text into the tool and check the results. You can review your word count, sentence count, and number of sentences.
It can also help you check:
Words per sentence
Average sentence length
Longest sentence
Average words per sentence
Sentences in your text
For better readability, aim to reduce unnecessary longer sentences. However, sentence length should not become a rigid rule. Some sentences may naturally need more words, especially in academic writing.
2. Use Active Voice to Make Content More Direct:
Active voice usually makes SEO copy clearer and more direct. It shows who performs an action, which helps readers understand the message quickly. For example, “Writers improve SEO content through editing” uses active voice. The subject performs the action directly. Passive voice shifts the focus toward the action. Sometimes, that approach makes sense. Use it when the person performing the action does not matter or remains unknown.
During editing, check whether passive sentences make your content less direct. Rewrite them when active voice improves clarity. However, do not remove every passive sentence. Good writing should sound natural and suit the context.
3. Make SEO Content Easy to Scan:
Online readers often scan content before reading every word. Therefore, your SEO content should make important information easy to find. Use descriptive H2s and H3s that clearly explain each section. Also, keep paragraphs focused on one main idea. Bullet points work well when you need to present several details. For example, use them for:
Steps and instructions
Features or benefits
Important facts
Related examples
You can also highlight important terms with bold text. However, avoid excessive formatting. Too much emphasis makes the page harder to scan. At the end, connect sections with simple transition words. This approach creates smoother movement between ideas.
4. Avoid Keyword Stuffing and Repetitive Language:
Keywords help search engines understand your topic. However, repeating the same phrase too often can make your content sound unnatural. Instead, place keywords where they fit naturally. Avoid using the same phrase in every paragraph or heading. You can also use related terminology when it improves clarity. However, never add unrelated terms simply to create keyword variety. Focus on useful information first. Then, review your content for unnecessary repetition.
5. Edit SEO Content for Readability Before Publishing:
Editing can reveal problems that you miss during the first draft. Therefore, read your article from the user’s perspective before publishing. Remove unnecessary words and filler wherever possible. Then, check sentence length, paragraph structure, grammar, and punctuation.
A simple readability checklist can include:
Check
What to Review
Sentences
Remove unnecessary longer sentences
Paragraphs
Keep ideas focused
Grammar
Fix unclear or incorrect wording
Transitions
Connect ideas naturally
Keywords
Remove forced repetition
Headings
Make them descriptive
You can also use a checker to identify potential readability issues. However, review the suggestions yourself. Automated results cannot always understand your intended meaning.
6. Combine Readability With Other SEO Content Practices:
Readability works best alongside other SEO practices. Clear sentences cannot replace useful and relevant information. First, match your content with search intent. Then, provide original information that answers the reader’s needs. Also, use descriptive headings and relevant links throughout the article. Internal links can guide readers to related pages. External links can support useful claims.
Before publishing, check these areas:
Search intent
Original information
Relevant internal links
Useful external links
Descriptive headings
Updated information
Grammar and punctuation
Conclusion
Readable SEO content helps users understand information more easily. It also creates a better experience across the page. Therefore, make readability part of your publishing workflow. Control sentence length and use active voice when appropriate. Keep paragraphs short and make important information easy to scan.
Avoid keyword stuffing and remove unnecessary repetition. Also, check grammar, punctuation, transitions, and structure before publishing. A sentence counter can help with the final review. It lets you check sentence length, word count, and structure. You can then improve unclear or overly long sentences before publishing your SEO content.
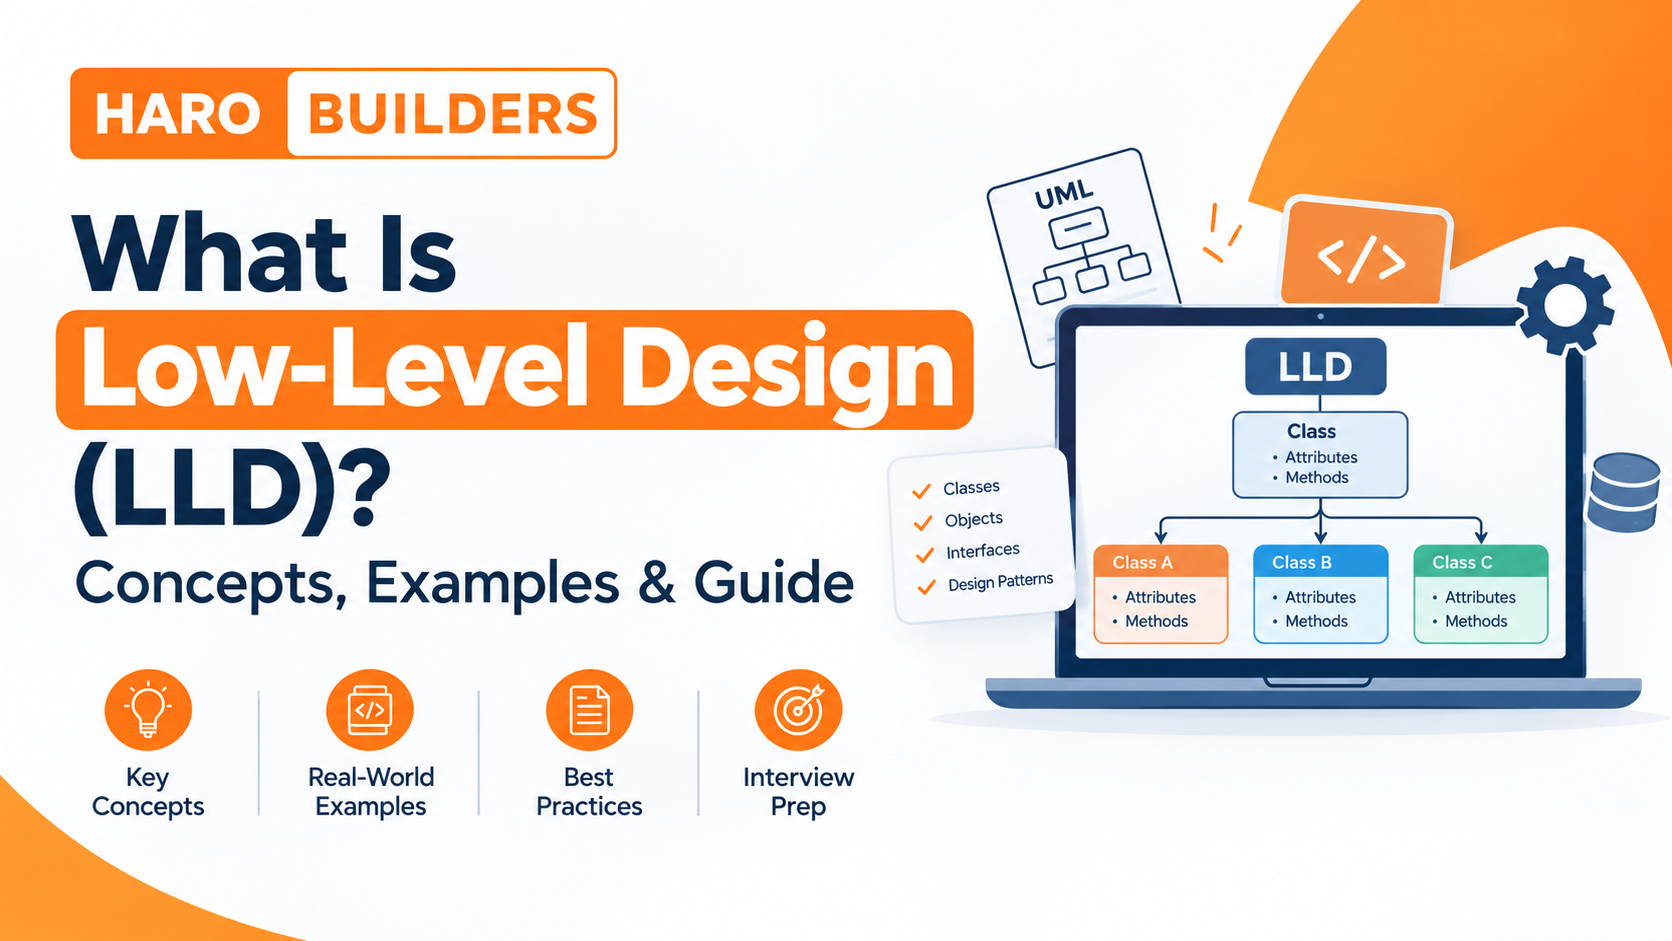
Low-level design (LLD) is the detailed design stage of software development where a system or component is broken down into classes, objects, interfaces, methods, relationships, data structures, and implementation-level behavior.
In simple terms, high-level design explains what major parts a system needs, while low-level design explains how those parts should be structured and work together in code.
LLD is useful in real software development as well as software engineering interviews. It helps developers think through responsibilities, dependencies, extensibility, and edge cases before implementation.
Quick Answer: What Is Low-Level Design (LLD)?
Low-level design (LLD) is the detailed, component-level design of software. It describes how individual modules or components should be implemented, including their classes, methods, interfaces, relationships, responsibilities, and interactions.
A good LLD acts as a bridge between a broader architecture and working code. It gives developers enough detail to understand how a component should behave without prescribing every line of the final implementation.
What Does LLD Mean in Software Engineering?
In software engineering, LLD focuses on the internal structure of a software component.
Suppose a high-level design says that an application needs a Notification Service.
HLD establishes the broader system structure. LLD takes an individual component or module and works out its internal design.
That distinction is also reflected in current software-engineering references, which describe LLD as detailed component-level design while HLD concentrates on the broader architecture.
How Does Low-Level Design Fit Into Software Development?
LLD should not be viewed as a completely separate activity from architecture.
A typical software-development process might look like:
Understand the requirements.
Identify the major system components.
Create the high-level architecture.
Break important components into smaller responsibilities.
Design classes, interfaces, methods, and relationships.
Review edge cases and dependencies.
Implement the design.
Test and refine it.
For example, an application’s HLD might identify an API server, database, authentication service, and payment service.
The LLD for the payment component could then define classes such as:
The exact classes depend on the requirements. LLD is not about creating as many classes as possible; it is about creating a structure that makes the required behavior clear and manageable.
For a broader understanding of how system components communicate, see HaroBuilder’s guide to client-server architecture.
What Are the Main Components of LLD?
There is no single mandatory LLD document format for every project. The details depend on the software being designed.
However, several concepts commonly appear in low-level design.
Classes and Objects
A class defines the structure and behavior that objects created from it can have.
For example:
Class: Order

Attributes:
- orderId
- customer
- items
- status

Methods:
- addItem()
- removeItem()
- calculateTotal()
- cancelOrder()
An object is a concrete instance of that class.
The important LLD question is not simply:
“What classes can I create?”
It is:
“What responsibilities should each class own?”
A well-designed class should have a clear purpose rather than becoming a container for unrelated functionality.
Interfaces and Abstraction
An interface can define a contract without forcing other components to depend on a specific implementation.
A payment processor can work with the PaymentMethod abstraction without needing separate logic for every implementation.
SOLID Principles
SOLID is a group of object-oriented design principles commonly applied when designing maintainable software.
Single Responsibility Principle
A class should have a focused responsibility rather than handling unrelated jobs.
For example, a User class should not necessarily handle authentication, email delivery, report generation, and database administration all at once.
Open/Closed Principle
Software components should generally be open to extension without requiring unnecessary modification to stable existing behavior.
Liskov Substitution Principle
Subtypes should behave consistently enough that they can be used where their parent abstraction is expected.
Interface Segregation Principle
Clients should not be forced to depend on methods they do not need.
Dependency Inversion Principle
Higher-level logic should depend on suitable abstractions rather than being tightly coupled to low-level implementation details.
SOLID principles are guidelines rather than mechanical rules. Applying them blindly can create unnecessary abstractions. Good LLD balances principles with the actual requirements.
Common LLD Design Patterns
Design patterns are reusable approaches to recurring design problems.
The important point is not to memorize patterns and insert them everywhere.
A pattern should solve a real problem.
Pattern
Typical problem
Example
Factory
Object creation varies
Payment provider creation
Strategy
Behavior can change
Pricing algorithms
Observer
Multiple components need updates
Notification events
Adapter
Interfaces are incompatible
External API integration
Decorator
Add behavior without changing the core class
Logging or optional features
Facade
Hide subsystem complexity
Simplified service interface
For example, suppose an application supports multiple pricing strategies:
Which object calls which component, and in what order?
Use-Case Diagram
Use-case diagrams are generally more focused on actors and their interactions with system functionality. They can help establish requirements before detailed component design.
The important thing is not to create diagrams for their own sake. A diagram should make a design easier to understand.
Low-Level Design Example: Notification System
A simple notification system provides a useful way to see LLD in practice.
Imagine the requirement is:
Users should be able to receive notifications through email or SMS, and the system should be easy to extend with additional notification channels later.
Step 1: Identify the behavior
The application needs to send a message.
Instead of creating separate high-level application logic for every channel, identify a common capability:
Suppose the business later asks for push notifications.
A poorly structured design might require changes throughout the application.
With a suitable abstraction, another implementation can be introduced:
PushNotificationSender
The exact implementation will depend on the system, but the important LLD principle is clear:
Design the abstraction around the behavior that genuinely needs to vary.
This is one reason interfaces, polymorphism, and appropriate design patterns appear so often in LLD discussions.
How to Create a Low-Level Design Step by Step
A practical LLD process can be more useful than memorizing definitions.
1. Understand the Requirements
Before creating classes, determine what the system actually needs to do.
Ask:
What are the main use cases?
Who interacts with the system?
What information must be stored?
What behavior can change?
What constraints matter?
Do not start by drawing classes.
2. Identify the Main Entities
Look for important concepts in the requirements.
For an online ordering system, these might include:
Customer
Order
Product
Cart
Payment
Shipment
These are candidates, not automatic classes.
Each candidate should be evaluated based on its responsibility.
3. Assign Responsibilities
Ask:
What should this component own?
For example:
Order
Track order information
Manage order state
Calculate order-related values
Payment
Represent payment information
Track payment state
PaymentProcessor
Coordinate payment processing
This separation prevents one class from becoming a “god object.”
4. Define Relationships
Next determine how components interact.
Ask:
Which class owns this data?
Which class uses this behavior?
Is the relationship permanent?
Can one component exist independently?
Should the relationship use an interface?
This is where association, composition, aggregation, inheritance, and dependency decisions become useful.
5. Identify Behavior That May Change
This is one of the most valuable LLD questions:
What is likely to vary?
Examples:
Payment methods
Notification channels
Pricing algorithms
Authentication providers
File-storage providers
Shipping strategies
Potentially changing behavior can often be isolated behind an interface or suitable abstraction.
6. Define Interfaces
Use interfaces when they provide a meaningful contract.
For example:
PaymentGateway

authorize()
capture()
refund()
Possible implementations might include:
CardGateway
BankGateway
WalletGateway
The goal is to reduce unnecessary coupling, not to create an interface for every class.
7. Apply Design Principles
Review the design using principles such as:
Encapsulation
Abstraction
Single Responsibility
Open/Closed
Dependency Inversion
Low coupling
High cohesion
Do not treat these as rigid checkboxes.
The right question is:
Does this principle improve this particular design?
8. Choose Design Patterns Only When Needed
If the design has a recurring problem that a pattern addresses, use one.
If the design does not need a pattern, don’t add one simply to make the diagram look sophisticated.
Overengineering can make a small application harder to understand.
9. Define Methods and State
At this stage, clarify:
Method responsibilities
Parameters
Return values
Object state
Valid transitions
Error conditions
Dependencies
For example:
Order

place()
cancel()
pay()
ship()
deliver()
You should also think about whether every transition is valid.
Can a delivered order be cancelled?
Can an unpaid order be shipped?
LLD should make these rules explicit where they matter.
10. Test the Design Against Change
This is one of the best ways to review an LLD.
Ask:
What happens if a new requirement is added?
For the notification example:
Current: Email + SMS
New: Push notification
If adding push notifications requires changing many unrelated classes, the design may have excessive coupling.
If a new implementation can be added behind an existing abstraction with limited changes, the design may be easier to extend.
The objective is not zero changes. A good design simply keeps necessary changes localized.
LLD vs HLD: What’s the Difference?
The easiest way to understand the difference is to ask what question each design answers.
Area
HLD
LLD
Main question
What major components does the system need?
How should a component be implemented?
Focus
Overall architecture
Detailed component design
Typical scope
System
Module, component, or feature
Examples
Services, databases, queues
Classes, methods, interfaces
Abstraction
Higher
Lower
Common artifacts
Architecture diagrams
Class/sequence diagrams
Main concerns
System structure and interactions
Responsibilities, behavior, relationships
Design patterns
Architectural patterns
Object-oriented/design patterns
Output
System-level blueprint
Implementation-level blueprint
Current technical references make a similar distinction: HLD focuses on system architecture, while LLD focuses on detailed components and their internal behavior.
Simple example
Imagine an e-commerce application.
HLD might define:
Web App
   ↓
API Layer
   ↓
Order Service
   ↓
Payment Service
   ↓
Database
LLD for the Order Service might define:
Order
OrderItem
OrderService
OrderRepository
OrderValidator
PaymentProcessor
The two levels are related, but they answer different questions.
Why Is LLD Important?
A thoughtful low-level design can make software easier to understand and change.
Maintainability
Clear responsibilities make it easier to locate and modify behavior.
Testability
Smaller, well-defined components can be easier to test independently.
Extensibility
Good abstractions can make future changes more localized.
Readability
A clear design helps developers understand how the code is organized.
Collaboration
Explicit interfaces and responsibilities can make it easier for multiple developers to work on different parts of a system.
Reusability
Well-designed components can sometimes be reused without copying large amounts of logic.
LLD does not automatically make software scalable, fast, or reliable. Those qualities also depend on architecture, implementation, infrastructure, data design, testing, and operational decisions.
For a broader explanation of software scalability and the difference between scalability and performance, see HaroBuilder’s scalability guide.
Is LLD Only for Interviews?
No.
LLD is a real software-development activity, not simply an interview exercise.
Developers use detailed design thinking when deciding how modules, classes, interfaces, and components should interact.
Interviews emphasize LLD because candidates can demonstrate how they break down an ambiguous problem into responsibilities, relationships, abstractions, and implementable components.
A good interview answer therefore shouldn’t be a memorized class diagram.
LLD interviews often test whether a candidate can translate requirements into a clean object-oriented design.
Common areas include:
Object-oriented programming
Classes and objects
Encapsulation
Abstraction
Inheritance
Polymorphism
SOLID principles
Design patterns
Class relationships
Interfaces
Extensibility
Error handling
Trade-offs
Interviewers may also ask candidates to design systems such as:
Parking lot
Vending machine
Elevator
Library management system
Notification system
Payment system
Task management system
Meeting scheduler
The exact problem is less important than the design reasoning behind it.
Common LLD Interview Questions
Here are useful questions to practice:
1. What is low-level design?
Be able to explain LLD in one or two clear sentences.
2. How is LLD different from HLD?
Explain the difference in scope, abstraction, artifacts, and purpose.
3. How would you identify classes?
Start from requirements, entities, responsibilities, and behavior rather than blindly turning every noun into a class.
4. When should you use an interface?
Explain the need for a stable contract or interchangeable implementations.
5. When should you use composition instead of inheritance?
Discuss the relationship and how behavior needs to vary.
6. How do you apply SOLID principles?
Give an example rather than simply reciting the acronym.
7. Which design pattern would you use?
First explain the problem. Then explain why the selected pattern fits.
8. How would your design handle a new requirement?
This tests extensibility and coupling.
9. How would you test the design?
Think about unit boundaries, component interactions, validation, and important edge cases.
10. How would you simplify an overengineered design?
This tests whether you understand that good LLD is not the same as maximum abstraction.
Common Low-Level Design Mistakes
Starting With Classes Too Early
Requirements should come before the class diagram.
Creating Too Many Classes
More classes do not automatically mean better design.
Overusing Inheritance
Inheritance can create rigid relationships when composition would be simpler.
Forcing Design Patterns
A pattern should solve a real problem.
Creating Giant Classes
A class that manages validation, persistence, notifications, payments, and reporting is usually carrying too many responsibilities.
Ignoring State
Objects often behave differently depending on their current state.
Ignoring Edge Cases
An apparently simple design can break when invalid input, duplicate requests, failures, or unexpected transitions occur.
Tight Coupling
If changing one implementation requires modifications across many unrelated components, the design may be too tightly coupled.
Overengineering
Designing for hypothetical requirements can make a simple system harder to maintain.
A good LLD should be detailed enough to make implementation clear without becoming unnecessarily complicated.
LLD Best Practices Checklist
Before considering an LLD complete, ask:
Have the requirements been clarified?
Are the main responsibilities clearly assigned?
Does each class have a focused purpose?
Are relationships between classes understandable?
Are interfaces used where they provide real value?
Is unnecessary coupling avoided?
Is the design reasonably cohesive?
Are changing behaviors isolated where appropriate?
Are design patterns justified?
Are important edge cases considered?
Are state transitions clear?
Can the design accommodate realistic changes?
Is the design understandable to another developer?
Can important components be tested independently?
If the answer is yes to most of these questions, the design is much easier to review and implement.
A Practical Way to Think About LLD
When you face a new design problem, don’t immediately ask:
“Which design pattern should I use?”
Start with:
What does the system need to do?
Then:
What are the important entities?
Then:
What responsibility belongs to each entity?
Then:
How should those entities communicate?
Then:
What behavior is likely to change?
Then:
What abstraction would make that change easier?
Only after that should you decide whether a particular design pattern or principle is useful.
This approach keeps the design connected to the actual requirements.
Key Takeaways
LLD means Low-Level Design.
It focuses on the detailed structure and behavior of software components.
LLD commonly deals with classes, objects, methods, interfaces, relationships, and implementation-level behavior.
HLD describes the broader architecture; LLD goes deeper into individual components.
OOP concepts and SOLID principles are important foundations for LLD.
Design patterns are useful when they solve recurring design problems.
UML diagrams can help communicate structure and interactions.
A good LLD should consider responsibilities, dependencies, state, extensibility, and edge cases.
LLD is useful in real software development as well as technical interviews.
The goal is not maximum abstraction. The goal is a design that is clear, maintainable, testable, and appropriate for the requirements.
For more technology and software-development resources, explore HaroBuilder.
Frequently Asked Questions About LLD
What is low-level design?
Low-level design is the detailed design of software components. It describes classes, objects, interfaces, methods, relationships, responsibilities, and interactions so developers can implement the required functionality.
What does LLD stand for?
LLD stands for Low-Level Design. It is also commonly described as detailed or component-level design.
What is LLD in software engineering?
LLD in software engineering focuses on how individual components or modules should be structured and implemented. It bridges broader architectural decisions and actual code.
What is the difference between LLD and HLD?
HLD focuses on the overall architecture and major system components. LLD focuses on the internal structure and behavior of individual components, such as classes, methods, interfaces, and relationships.
Is LLD the same as object-oriented design?
They overlap significantly, particularly in systems built using object-oriented programming. However, LLD can include more than object-oriented concepts, depending on the technology and system being designed.
What are the main components of LLD?
Common components include classes, objects, interfaces, methods, relationships, data structures, state, behavior, and sometimes UML diagrams or pseudocode.
What are common LLD design patterns?
Common examples include Factory, Strategy, Observer, Adapter, Decorator, and Facade. The appropriate pattern depends on the design problem rather than the popularity of the pattern.
Is LLD important for software developers?
Yes. Detailed design helps developers reason about responsibilities, dependencies, interactions, testability, and future changes before or during implementation.
Is LLD important for interviews?
Yes. LLD interviews commonly evaluate object-oriented design, SOLID principles, design patterns, class relationships, extensibility, and the ability to explain design decisions.
How do you create an LLD?
Start by understanding requirements, identify important entities, assign responsibilities, define relationships, identify changing behavior, create appropriate interfaces, apply relevant principles, select patterns where justified, and test the design against realistic changes.
Can LLD improve scalability?
LLD can contribute to maintainability and extensibility, but scalability is a broader system property. It also depends on architecture, infrastructure, databases, workload, performance, and operational design. HaroBuilder’s software scalability guide covers those broader considerations.
Conclusion
Low-level design is where software architecture becomes concrete.
Instead of stopping at statements such as “the system needs a payment service” or “the application needs notifications,” LLD asks what those components actually look like internally: which classes exist, what responsibilities they have, how they communicate, what interfaces they expose, and how the design can handle realistic changes.
The strongest LLD is not necessarily the most complicated one.
It is the design that makes the required behavior clear, keeps responsibilities manageable, limits unnecessary coupling, and gives developers a practical path toward implementation.
If you’re learning LLD for interviews, focus less on memorizing patterns and more on learning how to move from requirements → responsibilities → relationships → abstractions → implementation. That reasoning process is useful far beyond interview questions.
If you’re searching for Mogothrow77 software installation, the first step should not be running an installer. Public information about Mogothrow77 is inconsistent, and there is no clearly verified official developer, installer, or download channel established by reliable primary documentation. That means installation instructions found on third-party websites should be treated as reported guidance, not confirmed official documentation.
Before installing any unfamiliar software, verify its source, publisher, digital signature, file integrity, compatibility, and security status. If you cannot establish where the installer came from or who published it, it is safer not to run it.
What Is Mogothrow77 Software Installation?
Mogothrow77 software installation refers to the process described online for obtaining, setting up, and running software identified as Mogothrow77.
A typical software installation involves downloading an installation package, checking that the file is trustworthy, confirming operating-system compatibility, running the installer, selecting configuration options, and verifying the application after setup.
The important difference with Mogothrow77 is that publicly available information does not consistently establish the software’s official publisher or distribution channel. Several websites describe installation procedures, but their claims should not automatically be treated as official product documentation.
Is There an Official Mogothrow77 Installation Process?
This is one of the most important questions to answer before installing anything.
Current online sources describe Mogothrow77 as software and provide Windows, macOS, and Linux installation instructions. However, the published system requirements, installation details, and descriptions vary between websites.
For example, some third-party pages describe specific operating-system versions, RAM requirements, storage requirements, and installation packages, while other sources question whether an independently verifiable official installer or developer can be established.
For that reason, separate reported information from verified information.
Information
Current status
Mogothrow77 name appears online
Reported
Mogothrow77 is described as software
Reported
Clearly verified developer
Not independently established
Clearly verified official installer
Not independently established
Clearly verified official download channel
Not independently established
Exact system requirements
Conflicting across sources
Official source repository
Not independently established
Open-source status
Conflicting claims
This distinction matters because an installation tutorial can explain how an installer works without proving that the installer itself is authentic.
What Should You Check Before Installing Mogothrow77?
Before opening an unfamiliar executable or installation package, work through a basic verification process.
1. Verify the publisher
Look for the software publisher or developer and determine whether the identity can be independently confirmed.
A software name alone is not enough. If a download page provides no credible information about who created or maintains the software, treat that as a warning sign.
2. Check the download source
Look carefully at the domain hosting the installer.
Do not assume that a website using the software’s name is its official website. Check whether the same download source is referenced by reliable primary documentation, a verified developer account, or an established repository.
3. Check the installer file
Pay attention to the filename and extension.
Be especially careful with executable files received through:
Unknown websites
Random file-sharing pages
Unexpected email attachments
Unverified download links
Pop-ups or advertisements
4. Check the digital signature
On supported platforms, a valid digital signature can provide useful information about the publisher and whether a signed file has been modified.
Microsoft documents signature verification as a way to verify a file’s signer and integrity.
5. Verify the checksum when available
A SHA-256 checksum can help determine whether the installer you downloaded matches a trusted reference value.
A checksum is most useful when the expected hash comes from a trustworthy source.
Use your operating system’s security tools or a reputable security solution to scan an unfamiliar installer before executing it.
Do not treat a clean scan as proof that software is legitimate. It is only one part of the verification process.
7. Check requested permissions
Be cautious if an unfamiliar program immediately requests administrator privileges or access that does not appear necessary for its stated purpose.
Do not grant elevated permissions simply because an installation guide tells you to.
8. Confirm operating-system compatibility
Check the actual operating system and processor architecture before installing.
Avoid relying on conflicting third-party requirement lists as though they were official specifications.
9. Look for release information
A trustworthy software project normally has some form of identifiable release history, version information, documentation, or source of updates.
If none of these can be independently verified, proceed cautiously.
10. Stop when the source cannot be authenticated
This is the most important step.
If you cannot establish where the installer came from or who created it, do not feel compelled to continue simply because a third-party article provides installation instructions.
Mogothrow77 System Requirements: What Can Be Confirmed?
This is another area where publicly available information conflicts.
Some online guides publish specific requirements such as Windows versions, macOS versions, Ubuntu versions, RAM amounts, and storage requirements. Other sources provide different specifications.
Because these claims are inconsistent and a clearly verified official technical specification has not been established, they should not be presented as confirmed Mogothrow77 requirements.
Instead, use the requirements published by a verified developer or official documentation if such documentation becomes available.
Until then, treat third-party requirements as reported claims rather than authoritative specifications.
How Mogothrow77 Installation Is Described Online
If you already have a Mogothrow77 installer from a source you have independently verified, the general software installation workflow is usually straightforward.
The following describes a conventional installation workflow, not a claim that these are official Mogothrow77 instructions.
Step 1: Obtain the installer
Download the installation package only from a source you have verified.
Avoid downloading executable files from unrelated mirrors simply because they appear near the top of search results.
Step 2: Verify the file
Before opening the installer:
Check its filename.
Check its file type.
Check its publisher or signature where supported.
Compare its SHA-256 checksum when a trusted reference is available.
Scan the file with security software.
Step 3: Confirm compatibility
Check your operating system, processor architecture, available storage, and any documented dependencies.
Do not assume that requirements published by one third-party website are official.
Step 4: Review the installer
When the installer opens, read the publisher information and installation prompts carefully.
Pay attention to:
Software name
Publisher
Installation location
Additional components
Optional bundled software
Permissions
Privacy or license terms
Step 5: Choose the installation location
If the installer provides a choice, use a normal application directory unless official documentation recommends another location.
Avoid installing software into unusual folders simply to follow instructions from an unverified website.
Step 6: Complete the setup
Continue through the installation process only after reviewing the options.
If the installer displays unexpected warnings, unrelated software offers, or unusual permission requests, stop and investigate them before proceeding.
Step 7: Launch the application
After installation, open the application from the expected location.
Do not immediately provide sensitive credentials or personal information to unfamiliar software.
Step 8: Verify the installed software
Check:
Application name
Version
Publisher
Installation location
Security alerts
Unexpected programs or changes
The goal is to confirm that the program you installed matches the software you intended to install.
Windows Installation Considerations
If you encounter a Windows installer described as Mogothrow77, verify the file before running it.
Check the publisher information and digital signature where available. Windows may also display security warnings when an application comes from an unknown or untrusted source.
Do not automatically disable Windows security protections simply to make an unfamiliar installer run.
If the installer requires administrator privileges, determine why those privileges are needed before granting them.
macOS Installation Considerations
For a macOS installer, check whether the package comes from a verified source and whether the developer identity can be established.
macOS may display security warnings for applications that cannot be verified.
Do not bypass those protections simply because an installation guide instructs you to do so.
Also consider whether the application is intended for Intel-based Macs, Apple silicon Macs, or both if reliable documentation becomes available.
Linux Installation Considerations
Linux installation procedures depend heavily on the actual software distribution method.
A legitimate project may provide:
A package repository
A .deb package
An .rpm package
An AppImage
A container
Source code
Another documented distribution format
Do not invent package-manager commands or dependencies when official documentation does not establish them.
If a website provides a Linux command that downloads and executes an unknown script, inspect the command and its source before running it.
How to Verify a Mogothrow77 Installer Before Running It
Two terms frequently appear together in software verification: digital signatures and checksums.
They are related but serve different purposes.
Verification method
Main purpose
Digital signature
Helps verify the publisher and file integrity
SHA-256 checksum
Helps verify that a file matches a trusted reference
Security scan
Looks for potentially malicious indicators
Source verification
Establishes where the file came from
Version verification
Helps confirm that you received the expected release
A checksum is particularly useful when the expected hash comes from a trustworthy source.
For example, if a trusted software publisher publishes a SHA-256 value for an installer, you can calculate the hash of your downloaded file and compare the two values.
If they do not match, do not assume the difference is harmless. Stop and investigate.
A common mistake is assuming that a checksum and digital signature prove exactly the same thing.
They do not.
A checksum primarily helps you determine whether a file matches a known reference.
A digital signature can provide information about the signer and whether the signed content has been modified.
Neither should be considered a substitute for verifying the download source itself.
For an unfamiliar program, use multiple layers of verification instead of relying on one check.
Common Mogothrow77 Installation Problems
If you encounter an installation error, first determine whether the problem is technical or related to the source of the installer.
Installer will not start
Possible causes include:
Incompatible operating system
Corrupted download
Unsupported processor architecture
Missing dependency
Security software blocking the file
Damaged installation package
First verify that you obtained the installer from a trustworthy source.
Permission denied
The installer may require permissions that your current account does not have.
Do not automatically run unknown software as administrator.
Instead, verify the software and determine whether elevated permissions are genuinely required.
Unsupported operating system
If the installer does not work on your operating system, check for authoritative compatibility documentation.
Do not rely on a random compatibility claim from another website.
Missing dependency
Some software requires additional libraries or runtime components.
Only install dependencies from trustworthy sources. Avoid downloading individual DLL or library files from random websites.
Installation stops halfway
Possible causes include:
Corrupt installer
Insufficient storage
Missing dependency
Permission problem
Security software intervention
Incompatible operating system
Verify the installer before repeatedly downloading and running replacement files.
Software installs but will not open
Check the application version, system compatibility, security alerts, required dependencies, and installation logs where available.
If the source itself cannot be verified, reinstalling the application repeatedly may not be the appropriate solution.
What If the Mogothrow77 Installer Is Unverified?
This is where caution becomes especially important.
If you find an installer but cannot establish its source or publisher:
Do not:
Disable antivirus protection just to complete installation.
Run unknown files repeatedly.
Provide passwords to an unverified application.
Give administrator privileges without understanding why.
Download replacement DLL files from random websites.
Trust a website simply because it uses the Mogothrow77 name.
Assume that a detailed installation tutorial proves the software is legitimate.
Instead, look for authoritative documentation that identifies the developer and official distribution channel.
If that information cannot be established, the safest approach is to avoid executing the installer.
How to Verify the Installation After Setup
If you proceed with an installer from a verified source, perform a basic post-installation check.
Check the application
Confirm that:
The expected application was installed.
The version is what you expected.
The publisher information is consistent.
The application opens normally.
Check your system
Look for unexpected:
Applications
Browser extensions
Startup entries
Services
Security alerts
Network activity
Permission requests
An installation should not produce unexplained changes to your system.
Is Mogothrow77 Safe to Install?
There is not enough independently verified information to give Mogothrow77 a blanket safety assurance.
The more useful question is:
Can the specific installer you found be authenticated?
Check its publisher, source, signature, checksum, version, and security status.
If those checks cannot establish where the software came from, avoid installing it rather than treating third-party installation instructions as proof of legitimacy.
For broader context, HaroBuilder’s article on Mogothrow77’s open-source status discusses the uncertainty surrounding its source repository and licensing claims.
Frequently Asked Questions
Is Mogothrow77 software installation legitimate?
Public websites describe Mogothrow77 installation, but the available information does not independently establish a clearly verified official developer, installer, or distribution channel. Verify the specific source before running an installer.
Is there an official Mogothrow77 installer?
A clearly authenticated official installer has not been independently established from the available public information. Treat third-party download links cautiously.
How do I install Mogothrow77?
If you have a verified installer, the general process is to check its source and integrity, confirm compatibility, review the installation options, complete setup, and verify the installed application. Do not treat third-party instructions as official unless they can be independently confirmed.
What are the Mogothrow77 system requirements?
Published requirements vary between websites. Because those specifications conflict and an authoritative specification has not been independently established, they should not be treated as confirmed requirements.
Can Mogothrow77 be installed on Windows?
Several third-party pages describe Windows installation, but the existence of those instructions does not independently verify an official Windows release. Confirm the source and compatibility before running an installer.
Can Mogothrow77 be installed on macOS?
Some third-party pages describe macOS installation, but those claims should be verified against authoritative documentation before being treated as official.
Can Mogothrow77 be installed on Linux?
Some online guides describe Linux installation, but package formats, dependencies, and commands vary across distributions. Do not use unsupported commands from an unverified source.
Is Mogothrow77 safe to install?
The available evidence does not justify a blanket safety claim. Evaluate the specific installer and its source using publisher, signature, checksum, security-scan, and provenance checks.
How can I verify the Mogothrow77 installer?
Check its download source, publisher, digital signature, SHA-256 checksum when a trusted reference exists, file reputation, and security scan. If the source cannot be authenticated, do not run the installer.
What should I do if Mogothrow77 will not install?
First verify the installer source and integrity. Then check operating-system compatibility, processor architecture, permissions, storage, dependencies, and security alerts. Avoid unsafe fixes such as disabling security software or downloading random DLL files.
Does Mogothrow77 have an official GitHub repository?
An independently verified official repository has not been established from the available information. Claims about repositories should be checked against a verified developer identity.
Is Mogothrow77 open source?
Public claims about its open-source status are inconsistent. The existence of source-code claims alone does not establish that the software is officially open source.
Key Takeaways
Mogothrow77 software installation information is available online, but the sources are inconsistent.
A clearly verified official developer, installer, and download channel have not been independently established.
Published system requirements also conflict.
Do not treat third-party installation tutorials as official documentation.
Verify the source, publisher, digital signature, checksum, and security status before running an installer.
Never disable security protections simply to force an unfamiliar application to install.
If you cannot authenticate the installer, stopping the installation is safer than trying to work around the warning.
Conclusion
Installing unfamiliar software should begin with verification, not execution.
For Mogothrow77, this distinction is especially important because publicly available installation information does not consistently establish an authenticated official developer or distribution channel. Rather than copying an installation command from the first page you find, verify the specific installer and its source first.
If reliable official documentation becomes available, use that documentation for the exact operating-system requirements and installation procedure. Until then, treat third-party claims as claims, verify what you can, and avoid executing an installer that cannot be authenticated.
For more technology guides and software-related resources, visit HaroBuilder.
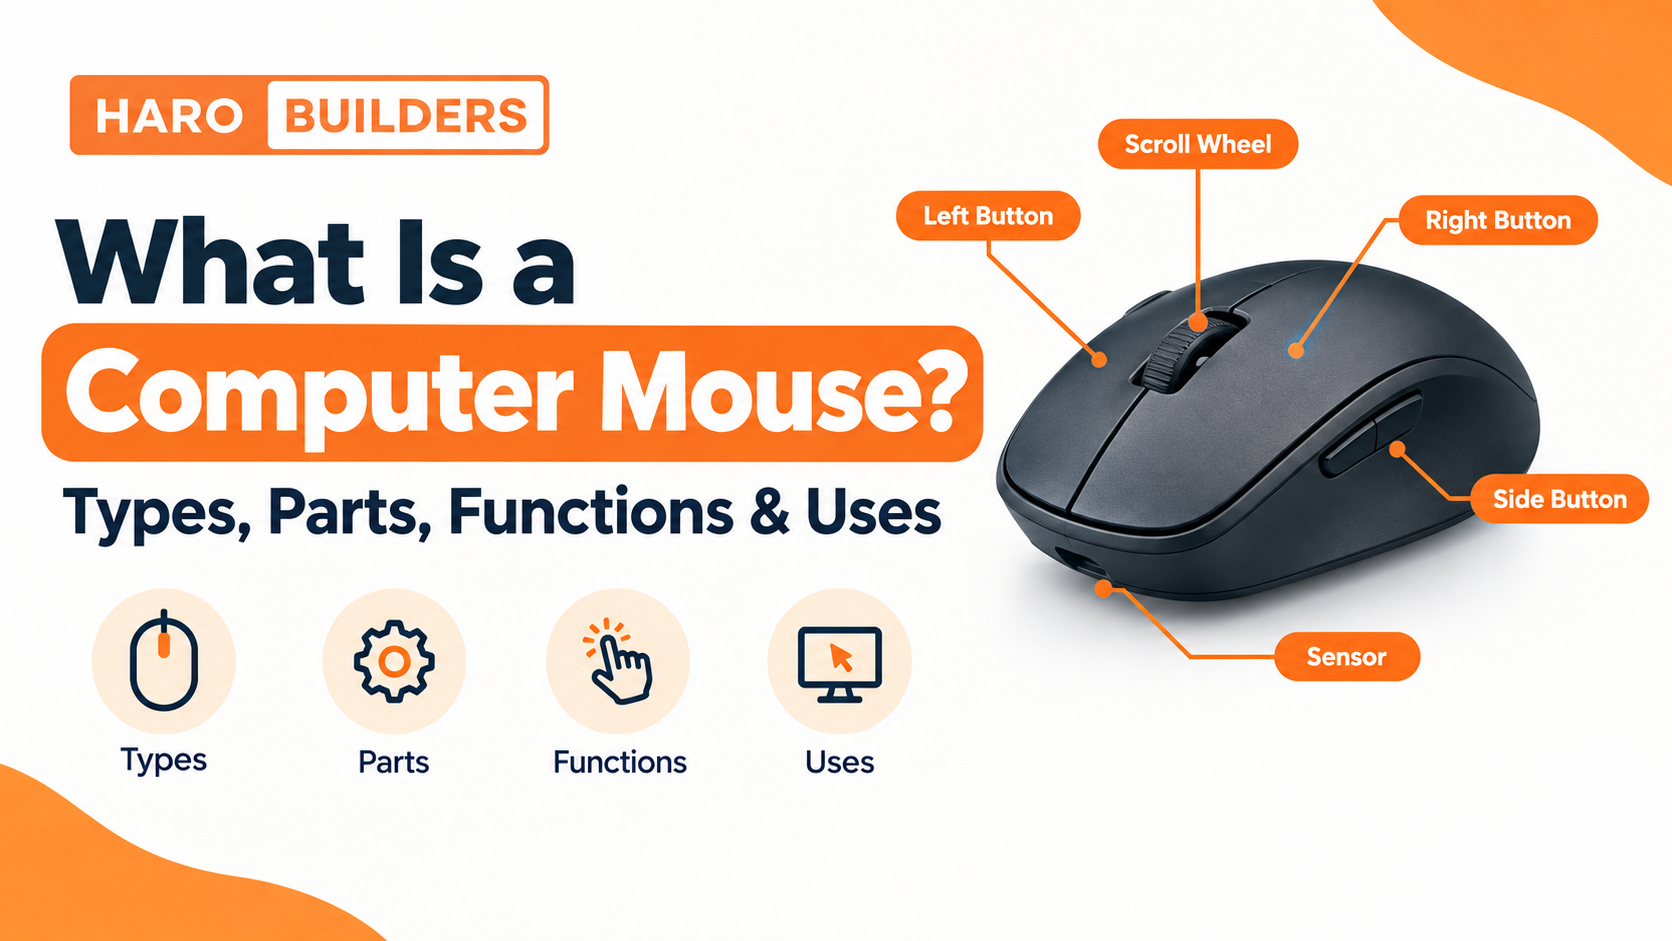
A computer mouse is a handheld pointing device that lets you control the pointer or cursor on a computer screen. By moving the mouse and using its buttons or wheel, you can select items, open files, click links, scroll through pages, drag objects, and interact with graphical interfaces.
Modern mice come in many forms. They can be wired or wireless, use optical or laser tracking, and be designed for general computing, gaming, comfort, portability, or specialized workflows.
This guide explains what a computer mouse is, how it works, its main parts, different types, functions, common uses, DPI, connectivity options, and how a mouse compares with a touchpad and trackball.
Quick Answer: What Is a Computer Mouse?
A computer mouse is an input and pointing device used to control a cursor or pointer on a computer display. It detects movement across a surface and sends movement and button information to the computer. The computer then uses that input to perform actions such as pointing, clicking, selecting, dragging, scrolling, and opening items.
In simple terms, a mouse provides a physical way to control and interact with objects on a computer screen.
What Is a Mouse in a Computer?
A mouse is one of the most common computer peripherals. It provides a convenient way to interact with software through a graphical user interface (GUI).
For example, when you move a mouse across a desk, the pointer usually moves across the screen. When you press the left button, the operating system or application receives a click input. When you rotate the scroll wheel, a webpage, document, or other interface can move vertically.
A mouse is therefore different from an output device such as a monitor. The monitor displays information to you, while the mouse sends physical actions from you to the computer.
A keyboard serves a similar input role, but it primarily captures key presses for text, commands, shortcuts, and navigation. If you want to understand how these two peripherals complement each other, see our guide to [what a keyboard does].
Why Is a Computer Mouse an Input Device?
A computer mouse is considered an input device because it sends information from the user to the computer.
The basic interaction looks like this:
User → Mouse → Computer → Operating System → Application
The mouse can send information about:
Movement
Button presses
Wheel movement
Additional side-button actions
Other controls supported by the particular mouse
The computer processes those inputs and translates them into actions on screen.
For example, moving the mouse may move the pointer, while pressing the right button may open a context menu.
What Does a Computer Mouse Do?
The main purpose of a mouse is to make computer navigation and interaction easier.
Common mouse functions include:
Function
What it does
Pointing
Moves the pointer to an item on screen
Clicking
Selects or activates an item
Double-clicking
Commonly opens files, folders, or applications
Right-clicking
Opens context-specific options
Scrolling
Moves through documents and webpages
Dragging
Moves an object while holding a button
Dropping
Releases a dragged object in a new location
Selecting
Highlights text, files, objects, or interface elements
Navigation
Helps users move around graphical interfaces
The exact result of an action depends on the operating system and application.
How Does a Computer Mouse Work?
Although a mouse looks simple, several components work together to turn physical movement and button presses into computer input.
The basic process is:
Physical movement → Sensor → Mouse electronics → Connection → Computer → Cursor or application action
1. The Mouse Detects Movement
When you move a modern optical mouse, its sensor repeatedly captures information about the surface beneath it.
The mouse’s internal electronics compare changes between successive readings to determine how the device has moved.
Older mechanical mice used a physical ball and internal rollers to detect movement. Modern mice generally use optical tracking technology instead.
2. The Sensor Processes Movement
The sensor is one of the most important components in a modern mouse.
An optical mouse uses light and an imaging sensor to track changes in the surface beneath the device. Laser mice use a laser-based tracking system.
The sensor does not simply “see” the cursor. It detects movement relative to the surface and reports movement information to the mouse’s electronics.
3. The Mouse’s Electronics Process the Input
A controller inside the mouse processes information from the sensor and buttons.
Depending on the mouse, the controller may also handle information related to:
DPI or sensitivity settings
Button states
Scroll-wheel movement
Polling behavior
Wireless communication
4. The Mouse Sends Data to the Computer
A wired mouse normally sends information through its cable.
A wireless mouse can communicate through a dedicated wireless receiver or Bluetooth, depending on its design.
The computer receives the mouse input and passes it through the operating system and relevant software.
5. The Cursor Responds
The final result is visible on screen.
Move the mouse and the pointer moves.
Click an item and the application responds.
Scroll the wheel and supported content moves.
Drag an object and the software can move it along with the pointer.
This is why a mouse is such an effective interface between physical movement and a graphical computer environment.
Parts of a Computer Mouse
Although designs vary, most traditional desktop mice contain several familiar components.
Mouse Part
Main Function
Left mouse button
Primary selection and activation
Right mouse button
Context menus and secondary actions
Scroll wheel
Scrolling and, on many mice, middle-clicking
Optical or laser sensor
Detects movement
Side buttons
Additional programmable or navigation commands
DPI button
Changes sensitivity on supported models
Cable
Provides connection and often power for wired mice
Wireless receiver
Connects some wireless mice to a computer
Battery
Powers many wireless mice
Left Mouse Button
The left button is normally the primary mouse control.
Common actions include:
Selecting files
Clicking links
Pressing interface buttons
Placing the text cursor
Starting a drag operation
A single left click and double-click can have different meanings depending on the operating system and application.
Right Mouse Button
The right button commonly opens a context menu.
The available options depend on what you right-click.
For example, right-clicking a file may display options for opening, copying, renaming, deleting, or viewing properties.
Scroll Wheel
The scroll wheel is normally positioned between the main mouse buttons.
Its most common purpose is scrolling through:
Webpages
Documents
Spreadsheets
Lists
Long menus
On many mice, pressing the wheel also works as a middle click.
Mouse Sensor
The sensor tracks movement across the surface.
Modern mice generally use optical tracking, while some products use laser tracking.
Sensor performance is one factor that affects how accurately a mouse can track movement.
Side Buttons
Many mice have one or more buttons on the side.
These may be assigned to actions such as browser back and forward navigation, application commands, or gaming controls.
Their behavior depends on the mouse and the software being used.
DPI Button
Some mice include a dedicated DPI button.
DPI is commonly used to describe mouse sensitivity or how much cursor movement results from physical mouse movement.
A higher setting can move the pointer farther with less physical movement, but higher DPI is not automatically better for every user or task.
Cable, Receiver, or Bluetooth Connection
A wired mouse uses a cable to communicate with the computer.
A wireless mouse may use:
A USB wireless receiver
Bluetooth
Another proprietary wireless connection
The connection method affects setup, portability, power requirements, and compatibility.
Types of Computer Mouse
One reason mouse terminology becomes confusing is that “type” can describe different characteristics.
For example, optical describes tracking technology, wireless describes connectivity, and gaming describes intended use and feature design.
A single mouse can belong to several categories at the same time.
For example:
A mouse can be optical, wireless, gaming, ergonomic, and Bluetooth-compatible.
That is why it is better to classify mice by their defining characteristic.
Types by Tracking Technology
1. Mechanical Mouse
Mechanical mice use a physical ball to detect movement.
As the ball rolls across a surface, internal mechanisms detect movement along different axes.
Mechanical mice were common in earlier generations of personal computers but have largely been replaced by optical tracking.
2. Optical Mouse
An optical mouse uses light and a sensor to track movement across a surface.
Optical mice are now common for general computing because they do not require the mechanical ball and rollers used by older mice.
They are available in wired and wireless designs and are used for everything from office work to gaming.
3. Laser Mouse
A laser mouse uses laser-based illumination for tracking.
Laser tracking can provide detailed surface tracking, although practical performance depends on the mouse, sensor, surface, firmware, and other design factors.
The important point is that laser does not automatically mean better.
Types by Connection
4. Wired Mouse
A wired mouse connects directly to the computer through a cable, commonly USB.
Advantages include:
No mouse battery required in typical designs
Simple connection
Consistent physical connection
No separate wireless pairing
The main drawback is cable management and reduced freedom of movement.
5. Wireless Mouse
A wireless mouse communicates without a physical data cable.
Many wireless mice use a small USB receiver connected to the computer.
Advantages include:
Cleaner desk setup
Greater freedom of movement
Easy portability
Potential considerations include battery or charging requirements and receiver compatibility.
6. Bluetooth Mouse
A Bluetooth mouse communicates directly with a Bluetooth-capable computer or device.
It can be useful with laptops and other devices where keeping a USB port available matters.
Bluetooth mice typically require pairing before use.
Types by Design and Purpose
7. Gaming Mouse
A gaming mouse is designed around features useful for computer games.
Depending on the model, it may include:
Adjustable sensitivity
Additional buttons
Customizable controls
High polling capabilities
Ergonomic shapes
Software for configuration
RGB lighting
Not every gaming feature is useful to every player, so the best configuration depends on the games and preferences involved.
8. Ergonomic Mouse
An ergonomic mouse is designed with comfort and hand positioning in mind.
Different ergonomic designs may change:
Hand position
Button placement
Grip style
Body shape
Wrist and forearm orientation
An ergonomic design that works well for one person may not feel comfortable to another.
9. Vertical Mouse
A vertical mouse places the hand in a more upright orientation than a conventional mouse.
The goal is generally to change how the hand and forearm are positioned during use.
This type can be worth considering for users who prefer a different grip or hand position.
10. Trackball Mouse
A trackball mouse remains mostly stationary while the user rotates a ball to control the pointer.
This can be useful where desk space is limited because the entire mouse does not need to travel across the surface.
Trackball designs require a different control technique from conventional mice.
Computer Mouse Types at a Glance
Mouse Type
Classified By
Typical Benefit
Mechanical
Tracking
Historical design
Optical
Tracking
Common modern tracking
Laser
Tracking
Laser-based tracking
Wired
Connection
Simple direct connection
Wireless
Connection
Cable-free use
Bluetooth
Connection
Convenient device pairing
Gaming
Purpose
Gaming-oriented controls
Ergonomic
Design
Comfort-focused shape
Vertical
Design
More upright hand position
Trackball
Design
Pointer control without moving the whole mouse
Optical vs Laser Mouse
Optical and laser mice are both designed to detect movement, but they use different tracking technologies.
Feature
Optical Mouse
Laser Mouse
Tracking method
Optical light and sensor
Laser-based tracking
Moving ball
No
No
Common use
General computing, gaming, office work
General computing and specialized use
Connection
Wired or wireless
Wired or wireless
Is one always better?
No
No
The right choice depends on the actual mouse implementation and the user’s needs rather than the label alone.
Wired vs Wireless vs Bluetooth Mouse
These terms are sometimes mixed together even though they describe connection methods.
Feature
Wired
Wireless Receiver
Bluetooth
Physical data cable
Yes
No
No
USB receiver
Usually not needed for data connection
Usually required
Not required
Battery
Usually powered through cable
Usually battery/charging
Usually battery/charging
Pairing
Usually no
Receiver-based connection
Bluetooth pairing
Portability
Good
Very good
Very good
Cable clutter
Higher
Low
Low
The right option depends on your computer, available ports, portability requirements, battery preferences, and workflow.
What Are the Functions of a Mouse?
A computer mouse supports several basic actions.
Pointing
Pointing means moving the cursor to a particular location on the screen.
This is the foundation of most mouse interactions.
Clicking
A click sends a button input to the computer.
A click can:
Select an item
Press a button
Place the text cursor
Activate a link
Trigger an application command
Double-Clicking
A double-click consists of two clicks performed within a short interval.
It is commonly associated with opening files, folders, or applications in desktop environments, although behavior varies by software.
Right-Clicking
A right click commonly opens a context menu containing actions relevant to the selected object or location.
Scrolling
Scrolling moves through content without requiring you to drag a scrollbar manually.
It is particularly useful on:
Webpages
Documents
Spreadsheets
Long lists
Code editors
Dragging and Dropping
To drag an object, you normally press and hold a mouse button, move the pointer, and release the button at the destination.
Drag-and-drop can be used for:
Moving files
Repositioning objects
Selecting text
Rearranging items
Working with graphics
Selecting Items
A mouse can select:
Files
Folders
Text
Images
Interface elements
Objects inside applications
Selection behavior depends on the software.
Executing Commands
Mouse actions can trigger commands in applications.
For example, clicking a toolbar button can activate a function without requiring a keyboard shortcut.
Common Uses of a Computer Mouse
Web Browsing
A mouse makes it easy to point at links, click buttons, scroll through webpages, select text, and interact with web applications.
Office Work
Mice are commonly used with:
Word processors
Spreadsheets
Presentation software
Email applications
Project-management tools
They are particularly useful when selecting cells, resizing objects, moving items, and interacting with menus.
Graphic Design
Design applications often require precise pointer control.
A mouse can be used for:
Selecting objects
Drawing paths
Resizing elements
Moving layers
Adjusting controls
Navigating tool panels
For some specialized tasks, a graphics tablet or pen can be more suitable than a mouse.
Gaming
Gaming mice can provide additional buttons, adjustable sensitivity, customization software, and other features designed around gaming.
The appropriate features depend heavily on the game genre and player’s preferences.
Education
Students can use mice to navigate educational software, online lessons, presentations, research websites, and interactive applications.
File Management
A mouse makes it easy to select, move, rename, copy, and organize files and folders.
Mouse vs Touchpad
A mouse and touchpad can perform many of the same basic tasks, but they provide different physical interfaces.
Feature
Mouse
Touchpad
Separate device
Yes
Usually built into a laptop
Physical movement
Move device
Move finger
Desk space
Usually required
No external space
Portability
Requires carrying separate device
Always attached to laptop
Gestures
Model/software dependent
Often strong gesture support
Gaming
Common
Less common
Precision
Often preferred for pointer-intensive work
Convenient for mobile use
Neither is universally better.
A laptop user may prefer a touchpad while traveling and a mouse when working at a desk.
Mouse vs Trackball
A conventional mouse is moved across a surface.
A trackball remains mostly stationary while you rotate a ball.
Feature
Mouse
Trackball
Device movement
Required
Mostly stationary
Desk space
More
Less
Learning curve
Familiar to most users
Different control method
Pointer control
Move mouse
Rotate ball
Portability
Usually simple
Varies by design
Trackballs can be useful in situations where moving a conventional mouse is inconvenient or desk space is limited.
What Is DPI on a Mouse?
DPI is commonly used as a measurement of mouse sensitivity.
In practical terms, changing the DPI setting changes how much the pointer moves in response to physical mouse movement.
For example, if you move a mouse the same physical distance:
A lower sensitivity setting generally produces less cursor movement.
A higher sensitivity setting generally produces more cursor movement.
Higher DPI is not automatically better.
A graphic designer, office worker, and competitive gamer may prefer different sensitivity settings because they use the pointer differently.
Some mice allow users to switch between multiple DPI settings using a dedicated button or software.
What Type of Mouse Should You Use?
There is no single mouse that is ideal for every user.
For Students
A basic wired, wireless, or Bluetooth mouse with comfortable controls is usually sufficient for browsing, documents, research, and general study.
For Office Work
Comfort, reliable tracking, button placement, and long-term usability may matter more than gaming-oriented specifications.
For Gaming
Look for features that actually match the games you play, such as additional buttons, adjustable sensitivity, appropriate shape, and configuration software.
For Graphic Design
Precise pointer control and comfortable movement are often important. Depending on the work, a mouse may be paired with or replaced by a drawing tablet.
For Small Desks
A compact mouse or trackball can help when there is limited room for moving a conventional mouse.
For Travel
A compact wireless or Bluetooth mouse can be convenient because it reduces cable clutter and takes less space in a bag.
If you’re building a laptop workstation, you can also see HaroBuilder’s guide to [tech gear for a MacBook Pro], which includes keyboards and mice among useful computer accessories.
Advantages of a Computer Mouse
Easy Navigation
A mouse provides direct pointer control and makes many graphical interfaces easy to navigate.
Precise Selection
A good mouse can make selecting small interface elements, objects, or text easier.
Fast Interaction
Clicking, double-clicking, scrolling, and dragging can be faster than navigating every command through menus or keyboard controls.
Wide Variety
There are mice designed for:
Office work
Gaming
Travel
Ergonomic use
Graphic work
General computing
Customization
Many modern mice allow users to customize buttons, sensitivity, lighting, or software controls.
Limitations of a Computer Mouse
Requires Space
A conventional mouse needs room to move across a surface.
Can Require Batteries
Wireless models usually need batteries or rechargeable power.
Cable Management
Wired models introduce a cable that may add clutter to a workspace.
Comfort Depends on Design
A mouse that feels comfortable to one person may not suit another person’s hand size, grip, or working habits.
Not Always Ideal for Every Device
Touch-first devices and some portable workflows may be easier to operate using a touchscreen or touchpad.
How to Maintain a Computer Mouse
A mouse does not usually require complicated maintenance.
Keep the Sensor Clean
Dust and debris around the sensor area can interfere with tracking.
Clean the Surface
Wipe the mouse carefully using an appropriate dry or lightly damp cleaning method recommended for the device.
Avoid allowing liquid to enter the mouse.
Use a Suitable Surface
A clean, consistent surface can help tracking performance.
A mouse pad can also provide a predictable surface and protect the desk.
Protect the Cable
If you use a wired mouse, avoid repeatedly bending or sharply twisting the cable.
Maintain Wireless Power
Recharge or replace batteries when necessary.
If the mouse suddenly stops responding, check its power state before assuming that the hardware has failed.
Who Invented the Computer Mouse?
The computer mouse is strongly associated with Douglas Engelbart and his research team at Stanford Research Institute.
The first prototype was built in the 1960s. The original design was a wooden device with wheels, and Bill English built the first prototype based on Engelbart’s concept.
Engelbart’s team later demonstrated the mouse publicly during the famous 1968 demonstration of the NLS system.
The Computer History Museum identifies Engelbart as a key developer of the mouse input device and documents the original SRI mouse and Bill English’s role in building the first prototype.
Are All Computer Mice the Same?
No.
Mice differ in:
Tracking technology
Connection method
Shape
Number of buttons
Sensor characteristics
Sensitivity settings
Size
Weight
Ergonomic design
Intended use
Software support
The important point is that these characteristics can overlap.
For example, a single product could be a wireless Bluetooth gaming mouse with an optical sensor, adjustable DPI, side buttons, and an ergonomic shape.
Frequently Asked Questions About Computer Mice
What is a computer mouse?
A computer mouse is a handheld pointing and input device that detects movement and button actions and sends that information to a computer. It is commonly used to control a cursor, select items, click buttons, scroll, drag objects, and navigate graphical interfaces.
What is a mouse used for?
A mouse is used for pointing, clicking, selecting, opening items, scrolling, dragging and dropping, navigating software, and interacting with graphical interfaces.
What are the main parts of a computer mouse?
Common parts include the left button, right button, scroll wheel, movement sensor, side buttons, and sometimes a DPI button. Wired models also have a cable, while wireless models may use a receiver and battery.
What are the functions of a mouse?
The main functions include pointing, clicking, double-clicking, right-clicking, scrolling, selecting, dragging and dropping, and executing commands within software.
How does a computer mouse work?
A modern mouse uses a sensor to detect movement across a surface. Its internal electronics process movement and button inputs and send the resulting information to the computer through a cable, wireless receiver, or Bluetooth connection.
What are the different types of computer mouse?
Mice can be classified by tracking technology, connection method, or design. Common examples include mechanical, optical, laser, wired, wireless, Bluetooth, gaming, ergonomic, vertical, and trackball mice.
What is an optical mouse?
An optical mouse uses light and a sensor to detect movement across a surface. Optical tracking is common in modern computer mice.
What is a wireless mouse?
A wireless mouse communicates with a computer without a physical data cable. Depending on the model, it may use a USB wireless receiver or another wireless technology.
What is a Bluetooth mouse?
A Bluetooth mouse communicates with a compatible computer or device using Bluetooth rather than a physical cable or conventional USB receiver.
What is DPI on a mouse?
DPI is commonly used to describe mouse sensitivity. Changing the DPI setting changes how much pointer movement results from a given amount of physical mouse movement.
Is a mouse an input device?
Yes. A mouse is an input device because it sends user actions such as movement and button presses to the computer.
Is a mouse better than a touchpad?
It depends on the user and task. A mouse can provide precise control and may be preferable for desktop work or gaming, while a touchpad is convenient because it is integrated into most laptops and requires no separate desk space.
What is the difference between an optical and laser mouse?
Both use sensor-based tracking, but they use different illumination technologies. Optical mice use optical light and a sensor, while laser mice use laser-based tracking. The better choice depends on the particular mouse and intended use rather than the label alone.
Key Takeaways
A computer mouse is a pointing and input device.
It lets users control a cursor and interact with graphical interfaces.
Modern mice commonly use optical tracking.
Mice can be classified by tracking technology, connection, design, and intended use.
Optical, laser, wired, wireless, Bluetooth, gaming, ergonomic, vertical, and trackball describe different characteristics or designs.
A mouse’s main controls include buttons, a scroll wheel, and a movement sensor.
DPI affects mouse sensitivity, but a higher DPI is not automatically better.
Wired mice connect through a cable, while wireless models may use a receiver or Bluetooth.
Different users may need different mice for office work, gaming, design, travel, or limited desk space.
A mouse and touchpad can perform many of the same tasks but offer different physical interfaces.
The most suitable mouse depends on the user’s device, workflow, comfort, and preferences.
Conclusion
A computer mouse is much more than a device that moves a pointer around a screen. It is an important input interface that converts physical movement and button actions into commands a computer can understand.
Modern mice differ considerably in how they track movement, connect to computers, fit the hand, and support different tasks. Understanding the difference between optical and laser tracking, wired and wireless connections, conventional and ergonomic designs, and general-purpose and gaming mice makes it easier to understand what each mouse is designed to do.
For everyday computing, the best mouse is not necessarily the one with the highest DPI or the largest number of features. The right choice depends on how you use your computer, how much space you have, what type of connection your device supports, and which design feels comfortable for your workflow.
Imagine a customer clicks Pay on an online checkout. The payment reaches the server, but the customer’s connection times out before the response comes back. The customer tries again.
Without proper protection, the system could process the payment twice.
This is where idempotency matters.
Idempotency allows a system to safely receive the same logical request more than once without producing the same unintended side effect repeatedly. It is particularly important for APIs, payment systems, distributed applications, webhooks, and any software that needs to retry requests after network or server failures.
In simple terms:
Idempotency means that repeating the same operation produces the same intended effect as performing it once.
HTTP defines idempotency in terms of the intended effect of repeated requests on server state. An idempotent request can still return different responses on subsequent attempts; for example, deleting an already-deleted resource may return a different status code the second time.
Quick Answer: What Is Idempotency?
Idempotency is a property of an operation that allows the same operation to be performed multiple times while producing the same intended result as performing it once.
For example, setting an account’s status to ACTIVE multiple times still leaves the account ACTIVE. By contrast, an operation that adds $10 to an account balance each time is not idempotent because repeating it changes the result repeatedly.
Idempotency is especially valuable when clients retry requests because of timeouts, lost connections, or temporary failures.
What Does “Idempotent” Mean?
Idempotent describes an operation that can be repeated without changing its intended outcome beyond the first successful application.
The distinction is simple:
Idempotency = the property or concept.
Idempotent = describes an operation that has that property.
Idempotent operation = an operation that can safely be repeated.
Idempotency key = an identifier used by an API to recognize repeated attempts at the same logical operation.
A useful way to think about it is:
One logical operation → multiple delivery attempts → one intended effect
This is different from saying that the server literally executes the underlying code only once. An implementation can receive or process multiple attempts while still ensuring that the externally visible business effect happens only once.
A Simple Idempotency Example
Consider two operations.
Operation A: Set a user’s status
Set status = ACTIVE
If the request is received once:
ACTIVE
If it is received five times:
ACTIVE
The intended final state is the same.
That makes the operation idempotent.
Operation B: Increase a balance
Add $10 to balance
Starting balance:
$100
One request:
$110
Two requests:
$120
Three requests:
$130
Repeating the operation creates another effect each time.
That operation is not idempotent.
The important question is therefore not:
“Did the request run more than once?”
The better question is:
“Does repeating the same logical operation create another unintended effect?”
Idempotent vs. Non-Idempotent Operations
Operation
Usually idempotent?
Why
Set user status to ACTIVE
Yes
Repeating it leaves the same state
Replace a resource with the same representation
Yes
Repeated replacement has the same intended effect
Delete a resource
Yes
Repeated deletion does not keep removing additional copies of the same resource
Read a resource
Yes
Repeating the request does not intentionally change the resource
Increment a counter
No
Every request increases the value
Add a new order
Not inherently
Repeating it can create multiple orders
Charge a payment
Not inherently
Repeating it can create multiple charges
Append an item to a list
No
Every request can add another item
The exact behavior depends on the operation’s semantics and implementation. HTTP’s definition focuses on the intended effect of repeated requests rather than requiring identical responses.
How Does Idempotency Work?
A typical idempotent API follows a process like this:
Client
   ↓
Send request + idempotency key
   ↓
Server checks the key
   ↓
Has this operation already been processed?
   ├── No → Process operation
   │        ↓
   │     Store result
   │        ↓
   │     Return response
   │
   └── Yes → Return stored result
The critical idea is that the server needs a reliable way to recognize that two requests represent the same logical operation.
For example:
Idempotency-Key: order-8f92c1
The client sends the request.
If the response is lost, the client sends the same logical request again using the same key.
The server can recognize:
order-8f92c1
as the same operation instead of treating the retry as an entirely new transaction.
Why Is Idempotency Important?
Idempotency becomes important when a request can be delivered more than once.
That can happen because of:
network interruptions
client timeouts
server timeouts
proxy failures
connection resets
user double-clicks
automatic retry mechanisms
message redelivery
worker restarts
load-balancer behavior
distributed-system failures
A client may not know whether a request failed before processing or after processing but before the response reached the client.
That distinction creates a dangerous situation.
Example
Suppose a customer submits:
POST /payments
The server receives it and successfully charges the card.
Before the response reaches the customer, the network connection fails.
The customer sees:
Request failed
But the payment actually succeeded.
If the client blindly sends another payment request, the system could create a duplicate charge unless the API has an appropriate mechanism for recognizing the repeated logical operation.
This is one reason idempotency is closely associated with reliable APIs and retry handling.
Idempotency in APIs
API requests commonly travel through several components:
Client
   ↓
Internet
   ↓
Load Balancer
   ↓
API Server
   ↓
Application
   ↓
Database
   ↓
External Service
Any part of that chain can fail or become unavailable.
A client may therefore retry a request without knowing whether the original operation completed.
For readers who want a broader explanation of how clients, servers, requests, responses, network dependency, and server availability fit together, HaroBuilder’s guide to client-server architecture provides useful background.
A robust API should distinguish between:
A new logical operation
and
another delivery attempt for an existing logical operation.
An idempotency key is one common way to make that distinction.
Which HTTP Methods Are Idempotent?
HTTP semantics classify several request methods as idempotent.
HTTP Method
Idempotent?
General reason
GET
Yes
Retrieves a resource
HEAD
Yes
Retrieves response metadata without a response body
OPTIONS
Yes
Requests communication options
PUT
Yes
Replaces the target representation with the supplied representation
DELETE
Yes
Repeated deletion has the same intended resource-state effect
POST
Not inherently
May create a new resource or trigger another side effect
PATCH
Not inherently
Applies a partial modification that may produce a new effect when repeated
MDN documents GET, HEAD, PUT, DELETE, and OPTIONS as idempotent, while POST and PATCH are not guaranteed to be idempotent.
Does an idempotent HTTP method have to return the same response?
No.
Consider:
DELETE /users/123
The first request might return:
200 OK
A later identical request might return:
404 Not Found
The response changed, but the intended server-state effect can still satisfy the HTTP definition of idempotency.
This is an important distinction because idempotency is about the intended effect, not identical responses.
What Is an Idempotency Key?
An idempotency key is a unique identifier attached to a request so the server can recognize repeated attempts at the same logical operation.
A simplified request might look like:
POST /api/orders
Content-Type: application/json
Idempotency-Key: 7d2f8c41-4f7c-4e35-a912-91c42a8b31d7
{
  "product_id": "P100",
  "quantity": 1
}
If the client does not receive a response, it can retry the request with the same idempotency key.
The key tells the server:
“This is another attempt to deliver the same logical operation.”
The Idempotency-Key header is currently documented by MDN as a mechanism that can be used to make POST and PATCH requests idempotent when supported by the server. MDN also notes that the header itself is not currently a standardized HTTP header and that server-specific requirements should be documented.
How Should an Idempotency Key Be Used?
A useful rule is:
New logical operation
        ↓
New idempotency key

Retry of same logical operation
        ↓
Same idempotency key
For example:
First attempt
Key: payment-abc123
Amount: $50
Retry
Key: payment-abc123
Amount: $50
The same key tells the server that both requests belong to the same logical operation.
But this is different:
Key: payment-xyz789
Amount: $50
That should normally represent a new operation.
What If the Same Key Is Used With Different Data?
This is an important edge case.
Suppose the first request is:
Idempotency-Key: abc123

{
  "amount": 50
}
Then a later request uses:
Idempotency-Key: abc123

{
  "amount": 500
}
The application now has a problem.
Is this:
a retry?
a modified request?
an accidental key reuse?
a potentially dangerous client bug?
A robust implementation should define what happens.
One approach is to store a request fingerprint or relevant request parameters alongside the idempotency key. MDN’s current documentation describes this pattern and notes that a server can reject reuse of the same key with a different request fingerprint.
How to Implement Idempotency
A production implementation generally needs more than simply adding an HTTP header.
Step 1: Identify operations that need protection
Start with operations where duplicate execution could cause harm.
Examples include:
creating an order
charging a payment
creating a subscription
sending a message
provisioning a resource
submitting a job
processing a webhook
creating a database record
Not every read operation needs an application-level idempotency key.
Step 2: Generate a unique key
The client generates a key for each new logical operation.
For example:
3f2504e0-4f89-41d3-9a0c-0305e82c3301
The exact format depends on the API.
The critical requirement is that the key should distinguish one logical operation from another.
Step 3: Send the key with the request
For example:
POST /api/orders
Idempotency-Key: 3f2504e0-4f89-41d3-9a0c-0305e82c3301
The client should reuse that key when retrying the same logical operation.
Step 4: Check whether the key already exists
The server checks its durable idempotency store.
Conceptually:
Does key X already exist?
If no:
Reserve key
Process operation
Store result
Return result
If yes:
Do not create the same side effect again
Return the previously stored result or defined duplicate response
Step 5: Make the check and reservation safe
This is where many simplistic implementations fail.
Imagine two identical requests arrive almost simultaneously:
Request A → check key → doesn't exist
Request B → check key → doesn't exist
Both could continue.
That can produce duplicate work.
The check and reservation therefore need appropriate concurrency control, such as a database uniqueness constraint, transaction, atomic insert, lock, or another mechanism appropriate to the architecture.
Step 6: Store enough information to handle retries
Depending on the application, the server may need to store:
idempotency key
operation status
request fingerprint
response status
response body
resource ID
timestamps
error state
expiration information
The exact storage strategy depends on the business operation.
Step 7: Define expiration
Idempotency records do not necessarily need to remain forever.
But expiration needs to be chosen carefully.
If the key disappears too quickly and the client retries later, the server might treat the retry as a new operation.
Therefore, the retention period should reflect:
maximum expected retry period
client behavior
queue delays
network conditions
business risk
operation lifetime
The server should document its key-expiration behavior when clients depend on it.
Now suppose the client never receives that response.
It retries:
POST /api/orders
Idempotency-Key: order-12345
The server recognizes the key.
Instead of creating:
Order #9002
it can return the result associated with the original operation according to the API’s defined behavior.
This is the practical value of idempotency.
Idempotency and Concurrent Requests
Retries are not the only source of duplicates.
Two requests can arrive at nearly the same time.
For example:
Request A ───────→ Server
Request B ───────→ Server
Both might use:
Idempotency-Key: abc123
A naive implementation might perform:
Check key
    ↓
Not found
    ↓
Process request
for both requests before either one has recorded the key.
That creates a race condition.
A safer design makes the creation of the idempotency record atomic.
For example:
Try to create unique key
        ↓
Success?
   ├── Yes → Process operation
   └── No  → Existing operation → handle as duplicate
This is one reason database constraints and transactions can be important parts of an idempotency design.
Idempotency in Payment Processing
Payments are one of the clearest examples.
Suppose:
Customer → Pay $100
The payment provider receives the request.
The charge succeeds.
But the response is lost.
The customer retries.
Without a way to identify the original logical operation, the second request could potentially create another charge.
With an idempotency mechanism:
Payment attempt
       ↓
Unique operation key
       ↓
Payment processed
       ↓
Result stored
       ↓
Retry with same key
       ↓
Original result recognized
This doesn’t remove every payment-system failure mode, but it gives the application a way to make repeated delivery safe for the operation it controls.
Idempotency in Webhooks
Webhooks create another common duplicate-processing problem.
A provider may send an event such as:
payment.completed
event_id = evt_123
Your application processes it.
Then the provider sends the same event again.
A webhook consumer can maintain a record of processed event identifiers:
evt_123 → processed
When the same event arrives again:
evt_123 → already processed
The application can avoid repeating the business side effect.
This pattern is especially useful when the delivery system uses retry behavior or otherwise permits duplicate delivery.
Idempotency in Microservices
Consider a simple architecture:
Order Service
      ↓
Payment Service
      ↓
Inventory Service
      ↓
Shipping Service
A failure can occur after one service has completed its work but before the caller receives confirmation.
That makes retries more complicated.
For example:
Order Service
     ↓
Payment Service
     ↓
Payment succeeds
     X
Response lost
The Order Service may retry.
If the Payment Service treats the retry as a completely new operation, the same payment could be attempted again.
A useful distributed-system design therefore carries a stable operation identity through the relevant processing chain.
AWS guidance similarly recommends propagating idempotency tokens through downstream services so duplicate messages do not create repeated side effects throughout a distributed workflow.
For readers who want to understand the broader request/response relationship and service dependencies first, HaroBuilder’s client-server architecture guide is a useful supporting resource.
Idempotency in Databases
Database design can also help enforce idempotent behavior.
Useful mechanisms can include:
unique constraints
transactions
upserts
conditional writes
atomic inserts
state transitions
processed-event tables
For example, suppose each payment has a unique external transaction ID.
The database can enforce:
transaction_id = unique
If the application receives the same transaction again, the uniqueness rule can prevent a second record from being created.
However, a unique database field alone is not always enough.
The complete operation may involve:
Database
+
Payment provider
+
Email service
+
Inventory system
The application still needs to reason about external side effects.
Idempotency vs. Retry
These concepts are related, but they are not the same.
Concept
Meaning
Retry
Attempt the request again
Idempotency
Make repeated attempts have the same intended effect
Idempotency key
Identifier used to recognize repeated logical requests
Timeout
A condition where the client stops waiting for a response
A retry mechanism without idempotency can be dangerous.
For example:
Request
  ↓
Timeout
  ↓
Retry
  ↓
Duplicate side effect
With idempotency:
Request
  ↓
Timeout
  ↓
Retry with same key
  ↓
Recognize existing operation
  ↓
Avoid duplicate effect
So:
Retry is the action. Idempotency is a property that makes repeated execution safe.
Idempotency vs. Exactly-Once Processing
These terms are often confused.
Idempotency does not automatically prove that the underlying code physically executed only once.
Instead, the goal is generally to ensure that repeated attempts produce the same intended business effect as one successful operation.
Consider:
Request A
   ↓
Operation starts
   ↓
Response lost
   ↓
Request B
Both requests may reach the system.
An idempotent design can recognize that both correspond to one logical operation and prevent a duplicate business effect.
Distributed systems make true exactly-once execution difficult because failures can occur between processing steps and acknowledgments. AWS discusses the distinction between at-most-once, at-least-once and exactly-once behavior in its reliability guidance.
A useful mental model is:
At most once
→ Don't retry aggressively

At least once
→ Retry until success is confirmed

Idempotent processing
→ Repeated attempts don't create repeated unintended effects

Exactly once
→ Stronger execution/processing guarantee that is difficult to achieve end-to-end
Do not use “idempotent” and “exactly once” as interchangeable terms.
Idempotency vs. Uniqueness
Uniqueness and idempotency solve different problems.
Uniqueness
Answers:
“Can two records have the same identifier?”
Example:
email must be unique
Idempotency
Answers:
“What happens if this logical operation is delivered more than once?”
For example:
Order request
+
same operation key
+
retry
=
same intended order effect
A unique database field can support an idempotent design, but uniqueness alone does not make an entire workflow idempotent.
Common Idempotency Mistakes
1. Generating a new key for every retry
If every retry gets a new key, the server may interpret every attempt as a new operation.
Correct:
New operation → Key A
Retry → Key A
Retry → Key A
Not:
New operation → Key A
Retry → Key B
Retry → Key C
2. Storing keys only in application memory
In a multi-server environment, one request might reach Server A while its retry reaches Server B.
If the idempotency state exists only in Server A’s memory, Server B may not know about the previous request.
The state therefore needs an appropriate shared or durable mechanism.
3. Ignoring concurrent requests
A simple:
SELECT
then
INSERT
pattern can have a race condition if two requests execute it simultaneously.
The reservation step should use an appropriate atomic mechanism.
4. Accepting different payloads under the same key
A key should not silently represent multiple unrelated operations.
The API should define how it handles:
same key + same request
versus:
same key + different request
Request fingerprinting or validation can help.
5. Expiring keys too early
If a retry arrives after the record has expired, the server may process it as a new operation.
Retention should therefore match realistic retry and recovery behavior.
6. Protecting only the first database write
Suppose an operation performs:
Create order
↓
Charge payment
↓
Send email
Preventing duplicate order records does not automatically guarantee that the payment or email side effects are protected.
The entire workflow needs appropriate failure handling.
7. Assuming an idempotent HTTP method solves everything
Using PUT or DELETE does not automatically make every application endpoint safe.
The application still needs to implement the intended semantics correctly. MDN explicitly notes that real-world servers are responsible for adhering to HTTP method semantics.
Idempotency Best Practices
A practical production checklist:
API design
Define which operations require idempotency.
Document retry behavior.
Document key requirements.
Define key expiration.
Decide how duplicate requests are handled.
Decide how conflicting payloads are handled.
Storage
Use an appropriate durable store.
Protect the key with a uniqueness mechanism.
Store enough information to identify the operation.
Consider the required retention period.
Concurrency
Make key reservation atomic.
Handle simultaneous requests.
Define an in-progress state.
Avoid check-then-act race conditions.
Error handling
Distinguish retryable failures from permanent failures.
Define what happens when processing is still underway.
Avoid creating a new logical operation during a retry.
Distributed systems
Propagate operation identity when necessary.
Make downstream operations retry-safe.
Track duplicate messages.
Consider external side effects.
Security
Avoid putting sensitive information directly into idempotency keys.
Validate key length and format.
Consider abuse and storage limits.
Do not treat an idempotency key as an authentication credential.
How to Test Idempotency
Don’t test only the happy path.
A useful test plan includes:
Test
Expected behavior
First request
Operation succeeds
Exact retry
No unintended duplicate effect
Retry after timeout
Existing logical operation recognized
Two concurrent requests
Only intended effect occurs
Same key, same payload
Treated as same operation
Same key, different payload
Defined conflict/error behavior
Server restart
Idempotency state remains available if required
Database failure
No inconsistent duplicate state
Downstream failure
Recovery behavior is defined
Expired key
Documented behavior occurs
Duplicate webhook
Event does not create another unintended effect
Testing concurrency is particularly important because an implementation can appear correct during sequential tests while still failing when two identical requests arrive simultaneously.
A Practical Idempotency Checklist
Before calling an API operation idempotent, ask:
Can the request be safely retried?
How does the server identify the logical operation?
Is an idempotency key required?
Is the key reused for retries?
Is key storage durable enough for the use case?
Is key creation atomic?
Are concurrent requests handled?
Are different payloads under the same key rejected or handled?
How long are keys retained?
What happens if processing is still in progress?
Are downstream operations also protected?
Are external side effects considered?
Are duplicate webhooks/messages handled?
Has the failure path been tested?
If several of these questions have no clear answer, the operation may not yet have a robust idempotency design.
Frequently Asked Questions About Idempotency
What is idempotency in simple words?
Idempotency means repeating the same logical operation does not create another unintended effect. For example, setting a user’s status to ACTIVE multiple times still leaves the user ACTIVE.
What does idempotent mean in programming?
An idempotent operation can be executed repeatedly while preserving the same intended outcome. The operation’s implementation determines whether it actually behaves idempotently.
Why is idempotency important in APIs?
APIs can experience timeouts, connection failures, retries, and duplicate requests. Idempotency helps prevent those repeated attempts from creating unintended duplicate effects.
What is an idempotency key?
An idempotency key is a unique identifier associated with a logical request. A client normally reuses the same key when retrying that operation so the server can recognize the repeated attempt.
Which HTTP methods are idempotent?
HTTP defines GET, HEAD, PUT, DELETE, and OPTIONS as idempotent. POST and PATCH are not guaranteed to be idempotent by HTTP semantics.
Is POST idempotent?
Not inherently. Repeating a POST request can create multiple resources or side effects. However, an application can design a POST endpoint to support idempotency, for example by using an idempotency key.
Is PATCH idempotent?
PATCH is not guaranteed to be idempotent by HTTP semantics. Whether a particular PATCH operation behaves idempotently depends on how the endpoint is designed and implemented.
Does idempotency mean the request runs only once?
No. Idempotency concerns the intended effect of repeated operations. Multiple attempts may reach or execute parts of a system while the application prevents duplicate business effects.
Is idempotency the same as exactly-once processing?
No. Idempotency can make repeated attempts produce one intended effect, but that does not automatically guarantee that every underlying processing step executes exactly once.
How does idempotency prevent duplicate transactions?
A system can associate a unique operation key with the transaction, store its processing state or result, and recognize subsequent attempts using the same key. The exact implementation depends on the transaction and architecture.
Key Takeaways
Idempotency means repeated execution has the same intended effect as one execution.
It is particularly valuable when requests can be retried.
Idempotency keys help APIs recognize repeated attempts at the same logical operation.
GET, HEAD, PUT, DELETE, and OPTIONS are defined as idempotent HTTP methods.
POST and PATCH are not inherently idempotent.
Idempotency is different from retry, uniqueness, and exactly-once processing.
Payments, orders, webhooks, and distributed systems are common use cases.
Durable state, atomic operations, request validation, and appropriate testing are important for robust implementations.
Final Thoughts
Idempotency is one of those software concepts that becomes much easier once you connect it to a real failure scenario.
A timeout does not necessarily mean an operation failed. A request may have reached the server and completed even though the client never received the response. If the client retries without a way to identify the original logical operation, duplicate side effects can occur.
A well-designed idempotent system treats retries as part of normal failure handling rather than as exceptional events.
The phrase “constraint on Bavayllo” is used online in more than one way. Some pages describe Bavayllo-related technical or performance limitations, while Bavayllo’s own published material focuses heavily on restrictions surrounding promotional content, platform policies, disclosures, and compliance.
That distinction matters.
If you are researching a Bavayllo limitation, it is better to identify the exact problem first than assume that every claim about CPU, RAM, API limits, storage, or performance is an official Bavayllo specification.
This guide explains what a constraint means in the Bavayllo context, which limitations can be discussed with confidence, how to distinguish documented information from unsupported claims, and how to troubleshoot a suspected constraint systematically.
Quick Answer: What Is a Constraint on Bavayllo?
A constraint on Bavayllo is a limitation, restriction, dependency, or condition that can affect how a Bavayllo-related system, workflow, or promotional activity operates. Bavayllo’s own article uses the term primarily in the context of promotional-content boundaries and platform compliance, including advertising claims, affiliate disclosures, sponsored content, landing pages, and policy enforcement.
Claims about specific Bavayllo CPU, RAM, storage, or API quotas should not be treated as official specifications unless they can be confirmed through appropriate first-party technical documentation.
What Is Bavayllo?
Bavayllo is presented online as a technology-focused information platform covering areas such as technology concepts, emerging devices, AI, automation, and troubleshooting.
Its published material also includes articles discussing Bavayllo-related tools, software, performance, and platform practices.
The important point is that the term Bavayllo does not automatically tell you what kind of constraint you are dealing with.
A restriction could involve:
promotional content
advertising or affiliate disclosures
platform policies
configuration
software behavior
resources
integrations
permissions
operational processes
The correct interpretation depends on the specific context.
For example, if the problem involves how promotional content is presented, Bavayllo’s own Constraint on Bavayllo article is directly relevant. If the problem is a generic server bottleneck, network issue, or software configuration problem, a general technical troubleshooting approach is more appropriate.
Why Is “Constraint on Bavayllo” Confusing?
The current online discussion uses the phrase inconsistently.
One interpretation treats constraints as technical limitations involving performance, resources, architecture, integrations, or scalability. Another interpretation, supported by Bavayllo’s own published page, focuses on promotional-content restrictions and compliance requirements.
There is also a broader problem with technology content on the web: a claim can be repeated across several websites until it appears authoritative even when the original documentation is unclear.
That is why it helps to separate three things:
What Bavayllo itself documents
What an independent source reports
What is simply a general technical assumption
These categories should not be treated as equivalent.
What Does “Constraint” Mean?
A constraint is a condition that limits what a system, process, platform, or user can do.
A constraint is not necessarily a bug.
For example:
A system may intentionally limit access for security reasons.
A platform may restrict certain promotional practices.
An application may require a particular configuration.
A server may have limited processing capacity.
An external API may impose usage restrictions.
A workflow may contain a step that limits throughput.
A useful way to think about it is:
Constraint = a boundary that affects what can be done, how it can be done, or how much can be done.
The next question is always:
What evidence shows that this particular constraint exists?
Which Bavayllo Constraints Are Actually Verified?
This is the most important distinction when researching the topic.
Bavayllo’s own article discusses promotional content and platform compliance. It specifically addresses areas such as affiliate marketing, sponsored content, promotional claims, disclosures, calls to action, landing pages, and responses to policy violations.
A safer evidence framework looks like this:
Potential constraint
Evidence status
Safe interpretation
Promotional-content restrictions
First-party discussion
Bavayllo discusses these boundaries
Affiliate disclosure
First-party discussion
Disclosure is presented as an important compliance consideration
Sponsored content
First-party discussion
Sponsored content is discussed within promotional compliance
Misleading promotional claims
First-party discussion
Bavayllo discusses misleading claims as a policy concern
Landing-page consistency
First-party discussion
Destination pages are discussed as part of compliance
CPU quota
Not established from the reviewed first-party page
Do not invent a specific limit
RAM quota
Not established from the reviewed first-party page
Do not invent a specific limit
Storage quota
Not established from the reviewed first-party page
Requires specific documentation
API rate limit
Not established from the reviewed first-party page
Verify through relevant API documentation
Universal performance ceiling
Not established
Requires technical evidence
This approach prevents a common SEO-content mistake: turning an assumption into a specification.
Types of Constraints You May Encounter
Not every category below should automatically be described as an official Bavayllo limitation. These are useful constraint categories for diagnosing a digital system or workflow.
1. Technical Constraints
Technical constraints can arise from software architecture, compatibility, processing capacity, dependencies, or infrastructure.
Examples include:
incompatible components
insufficient processing resources
software dependencies
configuration conflicts
unsupported environments
network limitations
If the problem involves how different components communicate, understanding client-server architecture can provide useful background.
2. Resource Constraints
A system can become limited when available resources do not match workload requirements.
Common resources include:
CPU
memory
storage
network bandwidth
database capacity
connection capacity
For example, RAM limitations can affect applications when available memory is insufficient for the workload. HaroBuilder’s guide to types of RAM in computers provides additional background on memory technologies.
The key point is that a general resource constraint should not automatically be described as a Bavayllo-specific limitation.
3. Configuration Constraints
A system may technically support a function but fail because the current configuration is incorrect.
Possible causes include:
incorrect settings
incompatible options
missing dependencies
incorrect permissions
outdated configuration files
conflicting components
This is why changing settings randomly is usually less useful than identifying the exact symptom first.
4. Integration Constraints
Modern systems often depend on other services.
An integration can introduce limitations through:
authentication
API availability
request limits
incompatible formats
version differences
network failures
external service changes
If an external service is responsible for the restriction, changing the local system may not solve the underlying problem.
5. Operational Constraints
Operational constraints come from the way a system or workflow is managed.
Examples include:
limited staff
manual processes
inefficient workflows
maintenance windows
insufficient monitoring
slow approval processes
These constraints may exist even when the underlying technology is functioning correctly.
6. Access and Permission Constraints
Some limitations are intentional.
A user may be unable to perform an action because:
the account lacks permission
authentication has failed
a role does not allow the action
a resource is restricted
a security policy blocks access
In these situations, increasing hardware resources would not solve the problem.
7. Policy and Compliance Constraints
This category is particularly relevant to Bavayllo’s own published discussion.
Bavayllo’s article focuses on promotional content and discusses issues such as affiliate relationships, sponsored content, disclosures, misleading claims, calls to action, and destination-page consistency.
These are fundamentally different from CPU or memory limitations.
A compliance restriction is usually addressed by changing the content, disclosure, claim, destination, or process—not by adding hardware.
How Constraints Can Affect Performance
A constraint can produce different symptoms depending on its source.
Symptom
Possible cause
What to investigate
Slow response
Resource or processing bottleneck
CPU, memory, database, application workload
Failed request
Integration or service problem
Error response, endpoint, authentication
Access denied
Permission or policy
Account role and applicable rules
Repeated software errors
Configuration or dependency problem
Version, settings, traceback
Workflow delays
Operational bottleneck
Process steps and queue times
Network timeout
Connectivity or service availability
Network path and server response
Promotional content rejected
Policy/compliance issue
Claim, disclosure, CTA, destination page
The same symptom can have multiple causes.
For example, “slow” does not automatically mean “not enough RAM.”
A server can respond slowly because of database contention, network latency, inefficient code, overloaded infrastructure, or an external dependency.
Common Causes of Constraints
Resource exhaustion
A system may run out of available CPU, memory, storage, or another resource.
Configuration problems
Incorrect settings can create behavior that looks like a technical limitation.
Compatibility problems
Different versions of software or dependencies may not work correctly together.
External service limitations
An application can be affected by restrictions imposed by another service.
Increased workload
A system that works well at a small scale may behave differently when traffic, users, requests, or data volume increase.
Permission restrictions
A missing role or permission can prevent an otherwise supported operation.
Policy changes
A platform can change its rules, turning a previously acceptable workflow into a restricted one.
Poor monitoring
Sometimes the constraint existed for a long time but was only noticed after it became severe.
How to Identify a Constraint on Bavayllo
Do not start by assuming the cause.
Use this process instead.
Step 1: Define the exact symptom
Write down what is actually happening.
For example:
an action fails
a page is rejected
a request times out
performance becomes slow
a feature is unavailable
content receives a policy warning
Avoid vague descriptions such as “Bavayllo is broken.”
Step 2: Capture the exact error
If an error message appears, save the complete message.
The exact wording may reveal whether the issue involves:
authentication
permissions
configuration
connectivity
dependencies
resources
policy
For software troubleshooting, the same principle applies to Python errors: identify the actual traceback and exception before changing the environment. HaroBuilder’s Dowsstrike2045 Python errors and fixes guide follows this evidence-first troubleshooting approach.
Step 3: Identify the affected component
Ask:
Where does the problem occur?
Is it:
the browser?
application?
server?
database?
API?
account?
network?
content?
policy layer?
This can dramatically narrow the investigation.
Step 4: Check first-party documentation
If the suspected limitation is supposedly an official Bavayllo restriction, look for documentation from the relevant first-party source.
Do not rely solely on a blog post repeating the same claim.
Step 5: Review logs and settings
Where available, inspect:
system logs
application logs
API responses
configuration
resource usage
authentication events
timestamps
Step 6: Reproduce the problem
If possible, determine whether the issue happens consistently.
A one-time failure may have a different cause from a predictable limit that occurs under the same conditions.
Step 7: Change one variable at a time
If you change five settings simultaneously, you may fix the problem without discovering what caused it.
Controlled testing makes the result easier to understand.
Step 8: Classify the constraint
Once you have evidence, classify the problem as:
technical
resource-related
configuration-related
integration-related
operational
access-related
policy-related
Step 9: Apply the appropriate solution
Only after identifying the likely constraint should you choose the remedy.
How to Manage or Overcome Bavayllo Limitations
The correct solution depends entirely on the type of constraint.
For technical constraints
Consider:
compatibility checks
supported versions
dependency updates
architecture changes
configuration review
For resource constraints
Consider:
measuring resource usage
optimizing workloads
reducing unnecessary processing
improving storage or memory capacity
distributing workloads where appropriate
Do not assume an upgrade is necessary before identifying the actual bottleneck.
For configuration constraints
Review:
settings
environment variables
permissions
dependency versions
configuration files
service connections
Document the original configuration before making major changes.
For integration constraints
Check:
authentication
endpoint configuration
request/response format
external-service availability
API documentation
rate or usage restrictions
For operational constraints
Look for:
repetitive manual work
unnecessary workflow steps
bottlenecks in approval
insufficient monitoring
poor scheduling
For policy constraints
Follow the applicable first-party policy.
Bavayllo’s own article recommends a proactive compliance process involving content audits, internal guidelines, pre-publication review, and monitoring of policy changes.
Bavayllo Constraints vs. General Software Constraints
One of the easiest ways to misunderstand this topic is to mix general software behavior with Bavayllo-specific facts.
Topic
General software concept
Bavayllo-specific conclusion
RAM
Applications can be affected by insufficient memory
A specific Bavayllo RAM quota needs evidence
CPU
Processing workload can create bottlenecks
A specific Bavayllo CPU limit needs evidence
API
APIs can impose rate or usage limits
A specific Bavayllo quota needs documentation
Storage
Software systems may have storage requirements
A specific Bavayllo storage ceiling needs evidence
Permissions
Access can depend on user roles
The actual restriction depends on the system
Configuration
Incorrect settings can cause failures
Diagnose the actual environment
Promotional content
Platforms can impose promotional restrictions
Bavayllo explicitly discusses this area
Disclosures
Sponsored/affiliate relationships may require disclosure
Discussed in Bavayllo’s own article
This distinction is especially important when publishing technical information.
A generic software principle can be useful without pretending that it is a documented Bavayllo specification.
What Should You Do If a Bavayllo-Related Claim Looks Wrong?
Start with the source.
Ask five questions:
Who originally made the claim?
Is the source first-party?
Is there supporting documentation?
Is the information current?
Can the claim be independently reproduced or verified?
If the answer to several of these questions is no, describe the information as an unverified claim, not as a confirmed limitation.
This approach is particularly useful for emerging technology topics where search results can contain multiple interpretations of the same term.
HaroBuilder’s article about latest tech information at BeaconSoft uses a similar verification-first approach when different online sources provide inconsistent descriptions of a technology-related entity.
Common Mistakes to Avoid
1. Treating every search result as official documentation
Search visibility does not automatically establish technical authority.
2. Inventing specific limits
Statements such as “Bavayllo only supports X GB of RAM” or “Bavayllo allows exactly X API requests” should not be published unless supported by appropriate documentation.
3. Confusing a bug with a constraint
A software bug may be fixed in a patch.
A policy restriction may require compliance.
A resource limitation may require optimization.
These are different problems.
4. Changing hardware before diagnosing the bottleneck
More CPU or RAM cannot fix an authentication failure or a policy violation.
5. Ignoring configuration
Many technical problems originate in settings rather than fundamental platform limitations.
A permission denial may be an intentional security control rather than a system failure.
For network-access scenarios, understanding how different firewall types control traffic can provide useful background.
A Practical Bavayllo Constraint-Checking Checklist
Before concluding that you have encountered a genuine Bavayllo limitation, check:
What exactly is failing?
What is the complete error message?
When did the problem begin?
Can the issue be reproduced?
Which component is affected?
Is the account authenticated?
Are the required permissions available?
Is the configuration correct?
Are dependencies compatible?
Is an external service involved?
Is there a documented limit?
Is the source first-party?
Could the issue be resource-related?
Could the issue be network-related?
Could the issue be policy-related?
What changed immediately before the problem appeared?
Can the suspected cause be tested independently?
This checklist is more useful than simply memorizing a list of supposed Bavayllo limits because it can be applied to different types of problems.
How to Improve Performance When a Real Bottleneck Exists
If your evidence shows that the problem is genuinely performance-related, start with measurement.
Look at:
CPU utilization
memory usage
storage performance
network latency
request volume
concurrent connections
database response time
application processing time
Then identify the resource that correlates with the slowdown.
For example:
High CPU + normal memory → investigate processing workload.
High memory + swapping or memory pressure → investigate memory usage.
Normal CPU and memory + slow database queries → investigate database performance.
👉Normal local resources + high network latency → investigate connectivity or external services.
Normal technical metrics + rejected promotional content → investigate policy and compliance rather than infrastructure.
A performance problem should be measured before it is optimized.
When a Constraint Is Actually a Policy Restriction
This deserves separate attention because it is directly relevant to Bavayllo’s published material.
Bavayllo discusses promotional-content boundaries including affiliate marketing, sponsored content, misleading claims, calls to action, disclosures, and landing-page considerations.
In that situation, “overcoming the constraint” should not mean finding a way around the rule.
The appropriate response is to understand the applicable policy and make the content compliant.
That can include:
clearer disclosures
accurate claims
appropriate promotional labeling
honest calls to action
consistent landing pages
documented review procedures
monitoring policy changes
Compliance is fundamentally different from bypassing a technical restriction.
Frequently Asked Questions
What does constraint on Bavayllo mean?
It refers broadly to a limitation, restriction, dependency, or condition associated with Bavayllo or a Bavayllo-related workflow. Bavayllo’s own article primarily discusses promotional-content and platform-compliance constraints, while other online sources use the phrase in broader technical contexts.
What are the common Bavayllo constraints?
Potential categories include technical, resource, configuration, integration, operational, access, and policy constraints. However, these categories should not automatically be treated as official Bavayllo specifications.
What are Bavayllo’s limitations?
The answer depends on the context. Bavayllo’s published material specifically discusses promotional-content restrictions and compliance considerations. Specific technical limits such as fixed CPU, RAM, storage, or API quotas require separate documentation before they can be treated as confirmed facts.
Are Bavayllo CPU and RAM limits officially documented?
A specific CPU or RAM limit should not be presented as an official Bavayllo specification unless it can be verified through appropriate first-party technical documentation.
How can Bavayllo constraints be managed?
First identify the type of constraint. Technical issues may require configuration or performance investigation, while policy constraints require compliance with the applicable rules. The correct solution depends on the evidence.
How do you overcome Bavayllo limitations?
You should not attempt to bypass legitimate security or policy restrictions. Instead, diagnose the limitation, verify its source, and use an appropriate supported solution such as optimization, configuration changes, workflow improvements, or compliance corrections.
Can configuration cause a Bavayllo-related problem?
Yes, configuration problems are a general source of software issues. A configuration error can sometimes look like a fundamental platform limitation, which is why the environment should be checked before concluding that the platform itself is responsible.
Are all constraints technical?
No. Constraints can be technical, operational, resource-related, access-related, or policy-related. Bavayllo’s own published article provides an example of a policy/compliance-oriented use of the term.
How can I verify a Bavayllo claim?
Look for the original source, check whether it is first-party, review the publication date, look for supporting documentation, and determine whether the claim can be independently confirmed.
What should I do if I encounter a Bavayllo-related error?
Record the exact error, identify the affected component, check the relevant documentation, review configuration and permissions, reproduce the problem where possible, and then test one potential cause at a time.
Is a constraint the same as a bug?
No. A constraint is a boundary or limitation, while a bug is generally unintended behavior in software. A bug can sometimes create symptoms that resemble a constraint, so diagnosis matters.
Why do different websites describe Bavayllo differently?
Search results can combine different interpretations, copied claims, general technical concepts, and first-party information. For that reason, the original source and context should be checked before treating a claim as an established Bavayllo specification.
Key Takeaways
“Constraint on Bavayllo” is not a term that should automatically be interpreted as one specific technical limitation.
Bavayllo’s own published material focuses substantially on promotional content and compliance-related restrictions.
General categories such as CPU, RAM, storage, configuration, integration, and scalability can describe common software constraints, but that does not make them confirmed Bavayllo-specific limits.
A technical problem should be diagnosed from its symptoms, logs, configuration, environment, and documentation.
Specific quotas should never be invented or repeated as facts without supporting evidence.
Policy restrictions should be addressed through compliance rather than attempted circumvention.
First-party documentation is the best starting point when verifying a platform-specific claim.
A useful constraint-management process is identify → verify → classify → test → resolve → document.
Conclusion
The phrase “constraint on Bavayllo” needs more context than a typical software-limit question.
The safest way to understand the subject is to separate documented information from general technical principles and unsupported claims. Bavayllo’s own published material provides clear discussion of promotional-content and compliance-related restrictions, while specific technical claims about resources or fixed system quotas require their own evidence.
If you are troubleshooting an actual problem, start with the symptom rather than the presumed cause. Capture the error, identify the affected component, check first-party documentation, review configuration and permissions, measure resources where relevant, and test one change at a time.
That approach gives you something more valuable than a generic list of supposed limitations: a repeatable method for determining whether a limitation is real, what is causing it, and what type of response is appropriate.
For more practical technology and SEO resources, explore HaroBuilder and its related guides.
When you download software, transfer data, or work with large files, you may see a long string of letters and numbers called a checksum. It may look like random text, but it serves a practical purpose: helping determine whether data has changed or become corrupted.
A checksum is a calculated value produced from digital data. By calculating the value again later and comparing the results, software can detect whether the data is consistent with the original.
But checksums are not all the same. CRCs, Internet checksums, MD5, SHA-1, and SHA-256 have different purposes and properties. A checksum can also help detect accidental corruption without necessarily proving that a file is authentic or safe.
This guide explains what checksums mean, how they work, where they are used, how to verify a file, and what a checksum mismatch actually tells you.
Quick Answer: What Is a Checksum?
A checksum is a calculated value derived from digital data and used to detect changes or errors. A checksum algorithm processes a file, message, or other data and produces a value. The same data can be processed again later. If the new value matches the expected value, the data is consistent with the reference; if it does not match, the data may have been corrupted, altered, or incorrectly processed.
What Does Checksum Mean?
The term checksum refers to a value calculated from a block of digital information.
Think of it as a compact way of representing the contents of data for comparison purposes. The calculation itself depends on the algorithm being used.
For example, imagine that a software publisher provides a file together with its SHA-256 value. After downloading the file, you calculate its SHA-256 value on your computer.
You might get:
Published SHA-256:
A1B2C3D4...

Downloaded file:
A1B2C3D4...
If the values match, the downloaded file produced the same cryptographic digest as the published reference.
If the values are different:
Published SHA-256:
A1B2C3D4...

Downloaded file:
F9E8D7C6...
the two inputs did not produce the same result. You should investigate the mismatch rather than assuming the download is correct.
The important point is that a checksum is not the original data. It is a calculated value used to help check the data.
How Do Checksums Work?
The basic checksum process is straightforward.
1. Start with the original data
The input could be:
A downloaded file
A network packet
A database record
A block of stored data
A software package
A transmitted message
2. Run the data through an algorithm
The algorithm processes the input according to its rules.
Different algorithms produce different types and sizes of values.
3. Generate the checksum value
The result is stored, transmitted, published, or otherwise made available for later comparison.
4. Recalculate the value
When the data is received or retrieved later, the same type of calculation can be performed again.
5. Compare the results
If the values match, the data is consistent with the expected result.
If they differ, something about the input or calculation is different.
The simplified process looks like this:
Original Data
     ↓
Checksum Algorithm
     ↓
Checksum Value
     ↓
Data Stored or Transmitted
     ↓
Checksum Calculated Again
     ↓
Compare Values
     ↓
Match or Mismatch
This is one reason checksums are useful for data integrity and error detection.
What Is a Checksum Used For?
Checksums are used in several areas of computing.
File integrity
Software distributors can publish a checksum alongside a download. Users can calculate the value of their downloaded file and compare it with the published value.
Data transmission
Checksums can help detect errors that occur while information moves between systems.
Network communication
Network protocols can use checksum mechanisms to detect certain transmission errors in packets.
Checksums can help identify whether stored data has changed or become corrupted.
Software distribution
Developers and publishers can provide hashes or checksum-like verification values so users can compare downloaded files with an expected value.
Backups
Integrity checks can help determine whether stored or copied data remains consistent with the reference data.
What Types of Checksums Are There?
There is no single checksum algorithm used for every situation. Different mechanisms are designed for different requirements.
Parity checks
A parity check is one of the simpler forms of error detection.
A parity bit can be added to a group of binary data so that the number of 1 bits follows a particular rule, such as even or odd parity.
Parity can detect some errors, but it has significant limitations. It is not designed to provide the stronger error-detection or cryptographic properties associated with more sophisticated algorithms.
CRC
CRC stands for Cyclic Redundancy Check.
A CRC processes data using polynomial arithmetic and produces a fixed-size value. It is widely used for detecting accidental changes and transmission errors.
CRCs are particularly useful when systems need efficient error detection rather than cryptographic security.
Internet checksum
Internet protocols have historically used checksum mechanisms to detect certain errors in transmitted data.
The Internet checksum is described in RFC 1071 and is used in networking contexts including protocols such as TCP and UDP. Its purpose is error detection rather than cryptographic protection.
This distinction matters: a network checksum should not automatically be treated as a security mechanism.
Cryptographic hashes
Cryptographic hash functions such as SHA-256 process data and produce fixed-length digests.
SHA-256 is part of the SHA-2 family standardized by NIST. Cryptographic hashes are designed with security properties that make them substantially different from simple error-detection checksums.
That is why a software publisher might provide a SHA-256 value for a download rather than a simple CRC.
Checksum vs Hash: What’s the Difference?
The words checksum and hash are sometimes used loosely, but they should not always be treated as synonyms.
A checksum is generally associated with detecting errors or changes in data. A cryptographic hash is designed with additional properties that make it suitable for security-related applications.
Feature
Checksum
Cryptographic Hash
Primary purpose
Detect errors or changes
Provide a strong data digest for integrity and cryptographic applications
Examples
CRC, Internet checksum
SHA-256, SHA-512
Security properties
Depend on the algorithm
Designed specifically for cryptographic security
Collision resistance
Varies and may be limited
An explicit design consideration
Common use
Transmission and storage error detection
File integrity, digital signatures and security systems
Encryption
No
No
The terminology can become confusing because people sometimes call any calculated file-verification value a “checksum.” When accuracy matters, identify the specific algorithm being used.
MD5 vs SHA-1 vs SHA-256
You may encounter several algorithm names when verifying files.
MD5
MD5 produces a 128-bit message digest.
It remains common in older software and legacy systems, but it is not considered suitable for modern security-sensitive cryptographic applications because practical collision attacks have been demonstrated.
It can still appear in older file-integrity workflows, but the security context matters.
SHA-1
SHA-1 produces a 160-bit digest.
It has also suffered from practical collision attacks and is no longer the preferred choice for new security-sensitive applications.
SHA-256
SHA-256 produces a 256-bit digest and belongs to the SHA-2 family.
It is widely used for modern integrity and security applications and is generally the more relevant algorithm to encounter when a current software project publishes a cryptographic hash.
NIST’s Secure Hash Standard documents the SHA family and its message-digest functions.
The key lesson is simple: do not judge an integrity value by its length alone. The algorithm that generated it matters.
How to Verify a File Checksum
Checking a downloaded file usually involves comparing a locally calculated value with the value supplied by a trusted publisher.
Step 1: Find the official reference value
Look at the software publisher’s official download or release page.
Find the checksum or hash corresponding to the exact file and version you downloaded.
Pay attention to the algorithm.
For example:
SHA-256
A1B2C3D4...
A SHA-256 reference should be compared against a SHA-256 calculation, not an MD5 value.
Step 2: Download the file
Download the exact file you intend to verify.
Make sure you know the:
Filename
Version
Operating-system build
Architecture
Release
A checksum comparison is meaningful only when you are comparing the same intended object.
Step 3: Calculate the checksum locally
Use an appropriate command or utility to calculate the value from your downloaded file.
Step 4: Compare the values
Compare the locally generated result with the publisher’s reference value.
If every character matches, the values are equal.
If even one character differs, the values do not match.
Step 5: Investigate a mismatch
Do not simply ignore a mismatch.
Check the:
Downloaded filename
Software version
Hash algorithm
Published reference value
Download source
Download completion
File size
If necessary, download the file again from the official source and repeat the verification.
How to Check a SHA-256 Checksum
SHA-256 is commonly used for file verification.
Windows
Windows PowerShell includes the Get-FileHash command.
The command calculates the SHA-256 hash of the specified file.
You can then compare the resulting Hash value with the publisher’s official SHA-256 value.
macOS
macOS includes the shasum command.
A typical SHA-256 calculation is:
shasum -a 256 /path/to/your-file.iso
The output can then be compared with the expected SHA-256 value.
Linux
Many Linux distributions provide sha256sum.
For example:
sha256sum /path/to/your-file.iso
Again, compare the resulting value with the trusted reference supplied for the exact file.
These commands calculate a hash; they do not automatically establish that the file is safe. The reliability of the comparison also depends on whether the reference value itself came from a trusted source.
What Does a Checksum Mismatch Mean?
A checksum mismatch means that the value calculated from your data does not match the expected value.
That can happen for several reasons.
The file was corrupted
A download or storage process may have altered the data.
The download was incomplete
An interrupted or damaged download can produce a different result.
👉You checked the wrong file
You may have downloaded a different version, operating-system build, or architecture.
You used the wrong algorithm
A SHA-256 value cannot be directly compared with an MD5 value.
The reference value is wrong
There can occasionally be a publishing or copying error.
The file was modified
The file may have been changed after the reference value was generated.
The source may be untrusted
If the file came from an unofficial or compromised source, a mismatch deserves particular attention.
A mismatch does not automatically tell you why the values differ. It tells you that the inputs or calculation results are not the same.
Can a Checksum Detect Corrupted Files?
Yes, a suitable checksum or hash can help detect changes caused by data corruption.
Suppose a file originally produces:
Expected:
7A92F1...
After transmission, the file is changed and produces:
Calculated:
C31D88...
The mismatch indicates that the received file is not producing the expected result.
However, a checksum does not repair corrupted data.
It also cannot necessarily tell you exactly where the corruption occurred.
The result is primarily a detection signal, not a recovery mechanism.
Are Checksums Secure?
This depends on the algorithm and how the reference value is obtained.
A basic checksum designed for accidental-error detection is not a substitute for a cryptographic security mechanism.
There are three different questions worth separating:
Did the data change?
A checksum or hash can help answer this.
Was the data transmitted correctly?
An appropriate error-detection mechanism can help identify transmission problems.
Did the data definitely come from the claimed publisher?
A checksum alone does not necessarily prove this.
For example, if an attacker can replace both a file and an unsigned checksum published alongside it, comparing those two values does not establish authenticity.
For security-sensitive distribution, additional mechanisms such as digital signatures and trusted distribution channels may be necessary.
This is also why a checksum should not be confused with encryption. Checksums and hashes do not hide the contents of a file.
👉Checksums in Computer Networks
Checksums have an important role in network communication.
When data moves across a network, errors can occur during transmission. Network protocols can use checksum mechanisms to help detect certain changes to transmitted information.
If the calculated result does not correspond to the expected value, the receiver can identify a checksum failure.
The exact behavior depends on the protocol and implementation.
Checksums are only one part of a much larger networking system. For additional background on how devices and systems communicate, see HaroBuilder’s guide to Wi-Fi and the Internet.
It is also useful to distinguish a checksum failure from a server availability problem. A network request can fail because a service is unavailable without that being a checksum problem; HaroBuilder’s guide to HTTP 503 Service Unavailable errors covers that separate issue.
Real-World Checksum Examples
Example 1: Downloading a software installer
A developer publishes:
SHA-256:
ABC123...
You download the installer and calculate its SHA-256 value.
If your result matches the published value, the file is consistent with that reference.
Example 2: Downloading a Linux image
Large operating-system images often come with published cryptographic hashes.
Because these files are large and important, verifying the downloaded image can help identify an incomplete or altered download.
Example 3: Backup verification
An organization can use integrity mechanisms to identify whether stored data differs from an expected version.
Example 4: Network transmission
A protocol can use a checksum to help detect accidental changes to transmitted data.
Example 5: Software troubleshooting
When working with unfamiliar software, verifying the download source and file integrity can be one part of a broader trust process. HaroBuilder’s existing guide to Dowsstrike2045 Python provides an example of the wider questions users may have when evaluating unfamiliar software.
Checksum vs CRC vs Hash
These terms overlap in everyday conversation, but they describe different concepts.
Technology
Typical purpose
Cryptographic security?
Parity
Basic error detection
No
CRC
Efficient error detection
No
Internet checksum
Network error detection
No
MD5
Legacy digest/integrity uses
No longer suitable for modern cryptographic security
SHA-1
Legacy cryptographic hashing
Not recommended for new security-sensitive applications
SHA-256
Modern cryptographic hashing
Yes, designed as a cryptographic hash
The table should not be interpreted as saying that every application of SHA-256 is automatically secure. Security depends on how the hash is used, where the reference value comes from, and what security property the system requires.
Common Checksum Mistakes
Assuming a matching checksum means a file is automatically safe
A match shows consistency with the reference value. It does not replace every other security control.
Comparing different algorithms
MD5, SHA-1, SHA-256 and CRC values are generated differently. Use the same algorithm as the published reference.
Checking the wrong file
A checksum for version 2.0 should not be compared against version 1.0.
Ignoring the source of the reference value
A hash published by an untrusted source provides a weaker basis for authenticity than a value obtained through a trusted channel.
Thinking checksums repair corruption
They generally help detect a problem. They do not reconstruct the original file.
Treating all checksums as cryptographic
Some checksum mechanisms are specifically designed for fast error detection and have no meaningful cryptographic security.
What Is a Checksum in Simple Terms?
A checksum is a calculated value used to check whether digital data is consistent with an expected result.
If the same algorithm produces a different value later, the data has changed in some way or the calculation conditions differ.
What Does a Checksum Tell You?
A checksum comparison tells you whether the calculated result matches the expected result.
A match provides evidence of consistency with that reference. A mismatch tells you that the results differ, but additional investigation is needed to determine why.
Is a Checksum the Same as a Hash?
Not always.
The terms are sometimes used interchangeably in casual discussions, but checksum algorithms and cryptographic hash functions can have very different purposes and security properties.
CRC and Internet checksum mechanisms are designed primarily for error detection, while cryptographic hashes such as SHA-256 are designed with stronger security properties.
What Is a Checksum Mismatch?
A checksum mismatch occurs when the value calculated from data differs from the expected checksum or hash value.
It may indicate corruption, an incomplete download, the wrong file, a calculation error, an incorrect reference, or a modification.
What Is SHA-256 Checksum?
A SHA-256 checksum is more precisely a SHA-256 hash or digest produced by applying the SHA-256 cryptographic hash function to data.
It produces a 256-bit digest and is widely used for file and data integrity applications.
What Is an MD5 Checksum?
An MD5 checksum is a 128-bit digest generated by the MD5 algorithm.
MD5 remains visible in legacy file-verification workflows, but it should not be treated as a modern cryptographic security mechanism because collision attacks against MD5 are well established.
How Do Checksums Detect Errors?
The algorithm produces a value based on the input data.
If the data changes and the algorithm produces a different result, comparing the new result with the expected value can reveal the discrepancy.
The ability to detect different types of errors depends on the algorithm.
What Happens When a Checksum Fails?
First, verify that you are checking the correct file with the correct algorithm.
Then check the download source, file version, reference value and file integrity.
If the mismatch remains, obtain a fresh copy from the trusted source and repeat the verification.
Key Takeaways
A checksum is a calculated value used to detect changes or errors in digital data.
Different checksum mechanisms have different purposes.
CRCs and Internet checksums are primarily associated with error detection.
Cryptographic hashes such as SHA-256 provide stronger security properties.
A checksum mismatch means the calculated result differs from the expected result.
A matching hash does not automatically prove that a file is safe or authentic.
Always compare the same algorithm and the exact intended file.
SHA-256 is generally more relevant to modern cryptographic file-integrity workflows than legacy MD5 or SHA-1.
Checksums can detect problems but generally do not repair corrupted data.
Final Thoughts
Checksums are a simple but important part of computing. They provide a way to compare digital data without comparing every byte manually, making them useful for file verification, storage, networking and error detection.
The most important distinction is that not every checksum provides the same level of protection. A simple error-detection checksum, a CRC and a cryptographic hash solve different problems.
When verifying a downloaded file, use the exact algorithm and reference value supplied by a trusted source. If the values match, the file is consistent with that reference. If they do not, stop and investigate the mismatch before relying on the file.
If you are trying to find out how much Mogothrow77 software is open source, the most accurate answer is that no independently verified percentage can currently be established from the available public evidence. The online claims are inconsistent: one Mogothrow77-branded page describes the software as proprietary and closed source, while other websites claim that some or all of the project is open source. Those claims are not supported by a consistently verifiable public repository and licensing record.
That distinction matters because software is not automatically open source simply because someone says the code is public, a product is free to use, or a few files are available online.
Quick Answer: How Much Mogothrow77 Software Is Open Source?
There is currently no reliable, independently verified percentage showing how much Mogothrow77 software is open source.
A Mogothrow77-branded page states that the software is proprietary and closed source, while several third-party pages make different claims about an open-source core or partially open code. However, the available evidence does not establish a verified source repository, license, and measurement methodology that would justify a specific percentage.
So, rather than claiming 0%, 60%, or 100%, the responsible answer is unknown until the relevant source code and licensing documentation can be independently verified.
What Does “Open Source” Actually Mean?
Open source has a more precise meaning than “the code is visible.”
The Open Source Initiative (OSI) explains that open-source software must meet requirements covering areas such as source-code availability, redistribution, and the ability to create derived works under qualifying licensing terms.
That means several conditions need to be considered together.
Source code availability
Developers need access to the appropriate source code, not merely screenshots, snippets, compiled binaries, or a small selection of files.
Modification rights
The applicable license must permit users to modify the software under its stated terms.
Redistribution rights
An open-source license also provides rights concerning redistribution and derived works, subject to the license.
A qualifying license
A project calling itself “open source” is not enough by itself. The actual license and its terms matter.
This is why checking the LICENSE file, repository ownership, source-code scope, and license terms is much more useful than relying on a sentence on a blog.
What Is Currently Known About Mogothrow77?
The public information surrounding Mogothrow77 is inconsistent.
A Mogothrow77-branded page currently describes the software as proprietary and closed source. It states that users cannot access, modify, or redistribute the underlying code.
At the same time, other websites have published claims suggesting that Mogothrow77 may have an open-source component, an open-source core, or a particular percentage of public code.
The problem is not simply that the claims disagree.
The bigger problem is that the underlying evidence is difficult to verify independently.
Current evidence summary
Question
Current evidence
Confidence
Is Mogothrow77 fully open source?
No reliable evidence establishes this
High
Is an exact open-source percentage verified?
No
High
Does a Mogothrow77-branded page claim proprietary status?
Yes
High
Is a verified public source repository established?
Not sufficiently established
High
Is an MIT license independently confirmed for Mogothrow77’s own code?
Not sufficiently established
High
Could Mogothrow77 use open-source dependencies?
Technically possible, but not proof that the product itself is open source
High
Can an exact open-source percentage currently be calculated?
Not from the available evidence
High
The key point is that a claim and a verification are not the same thing.
Why Are There Different Claims About Mogothrow77?
Search results for this topic contain several contradictory descriptions.
Some pages describe Mogothrow77 as proprietary.
Others suggest that it contains an open-source core.
Some discuss an MIT license.
Others avoid assigning a percentage altogether.
There are several reasons this can happen.
1. Repeated claims can look like evidence
A statement can appear on multiple websites without those websites independently verifying it.
If five blogs repeat the same unsupported claim, that does not automatically turn it into five independent sources.
2. “Public” can be confused with “open source”
A public file is not automatically open-source software.
The legal permissions attached to that file matter.
3. Dependencies can be confused with first-party code
A proprietary application may use open-source libraries.
That does not automatically make the application’s own source code open source.
4. Source-available software can be confused with open source
Some software allows users to inspect source code while imposing restrictions on commercial use, redistribution, or modification.
That is not necessarily the same thing as software distributed under a qualifying open-source license.
5. Percentage claims may use different measurements
One article might count files.
Another might count lines of code.
Another might count modules or functionality.
Those methods can produce very different percentages.
Is Mogothrow77 Fully Open Source?
There is currently no sufficiently reliable evidence establishing that Mogothrow77 is fully open source.
The strongest publicly visible first-party-style statement currently says the software is proprietary and closed source. However, that statement should still be distinguished from an independent technical audit because a company’s description of its own software is not the same thing as an external source-code examination.
The safer conclusion is therefore:
Mogothrow77’s full open-source status has not been independently established.
Is Mogothrow77 Proprietary or Closed Source?
The Mogothrow77-branded page describes the software as proprietary and closed source.
According to that page’s description, users cannot access the underlying source code or freely modify and redistribute it.
However, this should be reported as the site’s stated position, rather than presented as the result of an independent audit.
That distinction is important for trustworthy software research.
Can We Calculate a Mogothrow77 Open-Source Percentage?
Not responsibly without defining what “percentage” means and having access to the relevant source code.
Consider a hypothetical project containing:
100 files
60 public files
40 private files
It would be tempting to say the project is “60% open source.”
But that conclusion could be completely misleading.
What if the 40 private files contain almost all of the application’s core functionality?
The percentage would look very different if measured by:
lines of code
functionality
modules
first-party source
dependencies
executable components
repository files
This is why an open-source percentage needs both a defined methodology and verifiable source material.
Without those two things, a precise number can create a false impression of accuracy.
Does Mogothrow77 Have a Public GitHub Repository?
A public GitHub repository can be useful evidence, but simply finding a GitHub page with a similar name would not prove that it is the official Mogothrow77 source repository.
A legitimate repository should ideally be connected to the official project through several signals.
Check for:
An identifiable official organization or developer.
A link from the official website.
A clear README.
A LICENSE file.
Meaningful source code rather than only documentation.
Commit history.
Release history.
Version information.
Documentation that matches the software.
Evidence that the repository actually corresponds to the distributed product.
One third-party page has referenced a Mogothrow77 GitHub location, but another current source reports that the alleged repository location returns a 404 response. That means it should not be treated as verified evidence of an official open-source repository without stronger confirmation.
What License Does Mogothrow77 Use?
This is another area where caution is necessary.
Some third-party pages associate Mogothrow77 with the MIT License.
The MIT License itself is a recognized open-source license. But there is an important distinction:
The existence of the MIT License does not prove that Mogothrow77’s own software is MIT-licensed.
To establish that claim, you would want to see the actual license attached to the actual source code or authoritative project documentation.
A proper verification would ideally connect:
Official project → source repository → specific code → LICENSE file → published software version
Without that chain, the licensing claim remains unverified.
Open Source vs. Source Available vs. Proprietary
These terms should not be treated as interchangeable.
Model
Source visible?
Modification rights
Redistribution rights
License determines rights
Open source
Generally yes
Yes, under license
Yes, under license
Yes
Source available
Often
Depends on license
Depends on license
Yes
Proprietary
Usually restricted
Restricted
Restricted
Yes
The important difference is what the license permits, not simply whether someone can see some source code.
This is also why “public source code” and “open-source software” should not automatically be used as synonyms.
Can Proprietary Software Use Open-Source Components?
Yes.
This is common in software development.
A proprietary application can contain third-party open-source libraries.
For example, an application could use an open-source database driver, framework, utility library, or other dependency while keeping its own proprietary application code private.
That creates an important distinction:
Open-source dependency ≠ open-source application.
To determine how much of a product is genuinely open source, you would need to distinguish between:
first-party code
third-party libraries
frameworks
dependencies
generated code
configuration
proprietary business logic
That distinction is particularly important when someone claims that a product is “partially open source.”
How to Verify Whether Software Is Really Open Source
If you encounter a software project with unclear licensing, use a structured verification process.
Step 1: Find the official project
Start with the developer’s or organization’s official website.
Do not begin with random blogs.
Step 2: Locate the official source repository
Look for links to platforms such as GitHub, GitLab, or another recognized source-control service.
The repository should be traceable back to the official project.
Step 3: Check the LICENSE file
Look for an actual license file.
Common open-source licenses include:
MIT
Apache License 2.0
GPL
BSD licenses
The license should apply to the relevant source code.
Step 4: Identify the copyright holder
Check who owns or maintains the code.
A repository with an unrelated owner should not automatically be treated as the official project.
Step 5: Check the actual source
Determine whether the repository contains meaningful product source code.
A README or documentation repository alone does not establish that the underlying application is open source.
Step 6: Check release history
Compare repository releases with the versions of software being distributed.
This helps establish whether the public source corresponds to the actual product.
Step 7: Examine dependencies
Identify third-party libraries separately from first-party application code.
An application may depend heavily on open-source software while remaining proprietary itself.
Step 8: Read the license terms
Do not stop after seeing the license name.
Read the relevant permissions and restrictions.
Step 9: Check modification rights
Determine whether users are actually permitted to modify the relevant code.
Step 10: Check redistribution rights
Determine whether users can redistribute original or modified versions under the applicable license.
Step 11: Compare documentation with source
The repository, documentation, release notes, and distributed software should tell a consistent story.
If they do not, the project’s licensing status requires further investigation.
For another example of why source verification matters when researching unfamiliar software-related terms, HaroBuilder’s guide to Dowsstrike2045 Python separates verifiable information from unsupported online claims and explains how to check repositories and dependencies.
What Would Prove Mogothrow77 Is Open Source?
The strongest evidence would be a combination of technical and legal documentation.
Ideally, you would find:
an official public repository
identifiable ownership
actual Mogothrow77 source code
a recognized open-source license
a clear LICENSE file
version history
release information
documentation connecting the repository to the software
permissions covering modification
permissions covering redistribution
If only one of these exists, it may not be enough.
For example, a GitHub repository with no identifiable relationship to the software is weak evidence.
Likewise, a website saying “MIT licensed” without showing the relevant source and license is not enough to calculate an open-source percentage.
What Does Mogothrow77’s Open-Source Status Mean for Developers?
For developers, the most important issue is not the label itself.
It is the rights provided by the applicable license.
If the relevant source is genuinely open source, developers may have rights to:
inspect code
modify code
build derivative versions
redistribute code under applicable conditions
If the software is proprietary, those activities may be restricted.
That is why developers should verify the actual license before building a product, distributing modifications, or incorporating code into another project.
What Does It Mean for Businesses?
Businesses should be especially careful with licensing assumptions.
Before adopting software, organizations may need to know:
whether source code is available
whether modification is permitted
whether redistribution is permitted
whether commercial use is allowed
what attribution is required
whether dependencies have separate licenses
whether support is available
whether the software has an identifiable maintainer
A simple “open source” label does not answer all of those questions.
The license does.
Common Mistakes When Researching Open-Source Software
Mistake 1: Assuming free means open source
Free-to-use software can still be proprietary.
Mistake 2: Assuming GitHub means open source
A GitHub repository can contain proprietary, source-available, documentation-only, or other restricted material.
Mistake 3: Assuming public code means unrestricted code
Source visibility and legal permission are different concepts.
Mistake 4: Treating repeated blog claims as independent evidence
Multiple articles may simply repeat the same original claim.
Mistake 5: Assuming an MIT mention proves MIT licensing
The actual license must apply to the relevant code.
Mistake 6: Counting dependencies as first-party source code
Using an open-source library does not automatically make the application itself open source.
Mistake 7: Giving an exact percentage without methodology
A percentage without a defined measurement method can be misleading.
Mistake 8: Ignoring the version
Licensing can change between versions or between components.
Always check the relevant software version when licensing matters.
Mogothrow77 Open Source FAQs
Is Mogothrow77 open source?
Its open-source status cannot currently be established with enough independent evidence to give a definitive percentage. A Mogothrow77-branded page describes it as proprietary and closed source, while other online pages make conflicting open-source claims.
How much of Mogothrow77 is open source?
No independently verified percentage is currently established. Claims about specific percentages should be treated cautiously unless they provide the source repository, license, and measurement methodology used to calculate the number.
Is Mogothrow77 fully open source?
There is no reliable evidence establishing that Mogothrow77 is fully open source.
Is Mogothrow77 proprietary?
A Mogothrow77-branded page describes the software as proprietary and closed source. That is the project’s stated position, not an independent source-code audit.
Can you access Mogothrow77 source code?
There is currently insufficient independently verified evidence establishing a complete public source repository for Mogothrow77.
Does Mogothrow77 have a GitHub repository?
Online sources have referenced a possible repository, but the available evidence does not establish it as a verified official Mogothrow77 source repository. A reported 404 response further weakens that claim.
What license does Mogothrow77 use?
Some third-party pages claim an MIT license, but that claim has not been sufficiently tied to a verifiable official repository and license file.
Does Mogothrow77 use open-source libraries?
It is technically possible for proprietary software to use open-source dependencies, but there is not enough verified public documentation to identify Mogothrow77’s complete dependency structure.
Is source-available the same as open source?
No. Source-available software may let users inspect source code while imposing restrictions that do not satisfy the Open Source Definition.
Can proprietary software use open-source code?
Yes. Proprietary applications can use open-source libraries and components, subject to the applicable licenses.
Can Mogothrow77 code be modified?
That depends on the license governing the relevant source code. Without verified public source and licensing documentation, modification rights should not be assumed.
How can I verify a software license?
Find the official source repository, identify the relevant source code, locate the LICENSE file, verify ownership, review the license terms, and confirm that the license applies to the software version you intend to use.
Key Takeaways
There is currently no independently verified percentage showing how much Mogothrow77 software is open source.
A Mogothrow77-branded page describes the software as proprietary and closed source.
Other websites make conflicting claims about open-source components.
A repeated claim does not automatically become independently verified evidence.
A GitHub repository alone does not prove open-source status.
A software license must actually apply to the relevant source code.
Open-source dependencies do not automatically make an entire application open source.
“Source available” and “open source” are not necessarily the same.
An exact open-source percentage requires a clear methodology and verifiable source material.
The safest current conclusion is that Mogothrow77’s exact open-source scope remains unverified.
Conclusion
So, how much Mogothrow77 software is open source?
Based on the currently available public evidence, there is no independently verified percentage that can be stated confidently.
The public record contains conflicting descriptions. One Mogothrow77-branded page says the software is proprietary and closed source, while other websites claim that some or all of the software is open source. The problem is that those competing claims are not supported by a sufficiently transparent, independently verifiable chain of source code, repository ownership, licensing documentation, and release history.
For that reason, an exact number such as 0%, 60%, or 100% should not be presented as established fact without stronger evidence.
The better way to evaluate Mogothrow77—or any unfamiliar software—is to verify the actual source repository, license, ownership, version history, modification rights, redistribution rights, and third-party dependencies.
That approach produces a much more reliable answer than simply repeating whichever percentage appears most often in search results.
For more technology, software, SEO, and digital resources, explore the wider HaroBuilder resource library.
AI tools can help students understand difficult topics, review notes, prepare for exams, research subjects, improve writing, practice coding, and organize study sessions. But there is no single AI tool that is best for every student or every task.
The better approach is to choose a tool based on what you need to accomplish. A general AI tutor may be useful for explaining a difficult concept, while a source-grounded notebook can be better for studying your own course materials. A coding assistant serves a different purpose from a flashcard platform or presentation tool.
This guide compares useful AI tools for students in 2026 by their practical use cases, limitations, learning value, and availability. Features and access can change, so check the provider’s current terms before relying on a particular free or education plan.
Quick Answer: What Are the Best AI Tools for Students?
The best AI tools for students depend on the task. ChatGPT, Gemini, Gemini Notebook, Microsoft Copilot’s Study and Learn experience, Claude, Perplexity, Grammarly, Quizlet, Canva, and GitHub Copilot can each support different parts of a student workflow.
For studying, prioritize tools that explain concepts, ask questions, provide practice, and help you identify knowledge gaps rather than simply producing answers.
Student task
Useful AI tool/category
What it can help with
General studying
ChatGPT
Explanations, practice, review
Personalized study
Gemini
Lessons, quizzes, knowledge gaps
Course notes and PDFs
Gemini Notebook
Working with supplied study material
Guided learning
Microsoft Study and Learn
Step-by-step learning and practice
Long-form explanation
Claude
Reasoning, writing and conceptual help
Research
Perplexity
Research-oriented answers and source discovery
Writing improvement
Grammarly
Grammar, clarity and writing feedback
Flashcards and revision
Quizlet
Practice and memorization
Presentations
Canva
Visual assignments and presentations
Programming
GitHub Copilot
Coding assistance and explanations
The right choice depends on your subject, assignment, learning style, budget, privacy requirements, and your school’s AI policy.
How We Evaluated AI Tools for Students
A student-focused AI tool should not be judged only by how impressive its feature list looks.
For this guide, the more useful questions are:
Does it help you understand the subject?
Can it work with the type of material you actually study?
Does it encourage active learning?
Can you verify important information?
Does it have a useful free or student-access option?
Is it easy to use?
What are its limitations?
Can it fit within your school’s academic-integrity rules?
This matters because an AI system that instantly generates an answer may save time but provide less learning value than one that makes you work through the reasoning.
OpenAI’s current Study Mode, for example, is designed to guide students with questions, step-by-step explanations, practice problems, quizzes, and review of uploaded course materials rather than functioning only as an answer generator.
1. ChatGPT — Best for General Study Help
ChatGPT is useful when you need a flexible study assistant rather than a tool dedicated to one academic task.
Students can use it to:
Explain difficult concepts in simpler language
Break a large topic into smaller sections
Work through practice problems
Create quizzes
Generate flashcard-style questions
Review notes
Explain why an answer is correct or incorrect
Practice an oral exam
Brainstorm ideas before writing
Get feedback on a draft
Its current Study Mode is particularly relevant to students because it is designed around guided learning. It can ask questions, adjust explanations, work through homework or practice problems, and help students prepare for tests.
Best way to use ChatGPT for studying
Instead of asking:
“Give me the answer.”
try:
“Help me solve this step by step. Give me a hint first and let me attempt the next step.”
That changes the tool from an answer shortcut into a learning aid.
Limitation
AI responses can still contain mistakes. For important academic work, compare explanations with your textbook, lecture material, instructor guidance, or authoritative sources.
2. Google Gemini — Best for Personalized Study Workflows
Google has expanded Gemini’s education-focused capabilities in 2026.
Its newer study notebooks are designed around a student’s learning goal. Students can upload course materials, take a diagnostic quiz, identify knowledge gaps, and receive lessons that adapt as they progress. Google also describes integration between study notebooks and Gemini Notebook for working with course materials.
Useful student tasks
Gemini can be useful for:
Understanding course topics
Creating study plans
Reviewing class material
Practicing for tests
Identifying weak areas
Creating study questions
Working with uploaded learning materials
Best for
Students who want an AI learning environment that goes beyond one-off questions and moves toward a structured study workflow.
Limitation
Availability can vary by account, age, region, institution, and product rollout. Google has also introduced different education and personal-account experiences, so students should verify which features are actually available to them.
3. Gemini Notebook — Best for Studying Your Own Materials
Google renamed NotebookLM to Gemini Notebook in July 2026 while continuing its focus on research and learning. Google says the product is designed to work with notebooks and sources and has been used by students to transform notes into different learning formats.
This type of source-grounded workflow can be especially useful when you have:
Lecture notes
Course readings
PDFs
Study guides
Syllabi
Research material
Instead of asking an AI about an enormous subject generally, you can give it the material you are actually studying and ask questions about that material.
Example workflow
Add your course material.
Ask for a concise topic outline.
Identify concepts that need more explanation.
Ask questions about those concepts.
Generate practice questions.
Test yourself without looking at the answers.
Review the areas where you struggled.
Google says its newer study-notebook experience can use uploaded class materials, diagnostic quizzes and adaptive lessons, making this a particularly relevant area for students preparing for exams.
4. Microsoft Copilot Study and Learn — Best for Guided Learning
Microsoft’s Study and Learn experience is designed specifically around learning rather than simply returning answers.
Microsoft describes it as a learning-focused experience that helps students understand concepts, solve problems, improve writing, and participate in guided practice.
What makes it useful for students?
A learning-first system can encourage:
Guided questions
Practice
Retrieval
Step-by-step problem solving
Independent thinking
Writing improvement
Microsoft says Study and Learn is available through eligible Microsoft 365 Education environments, with access and age requirements that can vary by institution.
Best for
Students whose schools or universities already use Microsoft education products.
Limitation
Institutional access is important. A feature available to a school account may not be available through an ordinary personal account.
5. Claude — Useful for Explanations, Reasoning and Writing Support
Claude can be useful when you need detailed explanations, structured reasoning, brainstorming, or writing feedback.
Anthropic’s education offering also includes a learning mode designed to guide students through reasoning rather than simply giving them answers.
Student use cases
Understanding difficult concepts
Comparing ideas
Brainstorming
Reviewing writing
Breaking down complex material
Working through reasoning-heavy questions
Best for
Students who need detailed discussion and conceptual support.
Important limitation
As with any generative AI system, students should verify factual claims and citations before using them in academic work.
6. Perplexity — Best for Research-Oriented Searching
Research is different from ordinary studying.
When researching a subject, you often need to know:
Where did this information come from?
What is the original source?
Is this claim current?
Can I verify it?
Are multiple sources saying the same thing?
A research-oriented AI search tool can be useful for discovering sources and getting an initial understanding of a topic.
But students should not treat an AI-generated citation as automatically correct.
A safer research workflow
AI discovery → Open original source → Read the source → Verify claim → Cite the original
This is particularly important for essays, dissertations, reports, and academic research.
Do not paste an AI-generated bibliography into an assignment without checking whether every cited paper, author, title, URL, and quotation actually exists.
7. Grammarly — Best for Writing Improvement
Writing assistants can be useful after you have developed your own ideas.
A productive student workflow is:
Write your draft → Review the argument → Use an editor for clarity → Make your own final decisions
Useful areas include:
Grammar
Spelling
Sentence clarity
Tone
Conciseness
Readability
The goal should be to improve your writing rather than outsource the thinking behind the assignment.
Best for
Students who already have a draft and want help making the writing clearer and easier to understand.
8. Quizlet — Best for Flashcards and Revision
Flashcards can support active recall, which is useful when learning facts, terminology, definitions, formulas, and concepts.
Quizlet is especially relevant for students who prefer:
Flashcards
Repeated review
Practice questions
Vocabulary study
Definition-based learning
The key is not simply generating hundreds of cards.
A smaller set of accurate, high-value questions can be more useful than a giant automatically generated deck.
Better flashcard format
Instead of:
“Photosynthesis — definition?”
use questions that require recall:
“What are the two major stages of photosynthesis, and what happens during each?”
The second format forces you to retrieve the concept rather than recognize a definition.
9. Canva — Best for Presentations and Visual Assignments
Students frequently need to convert information into:
Presentations
Posters
Infographics
Visual reports
Class project materials
AI-assisted design tools can help with the structure and visual presentation of those projects.
But design automation should not replace the student’s responsibility for:
Accurate information
Appropriate citations
Clear argument
Original analysis
Correct attribution
Use AI to improve presentation, not to disguise weak research.
10. GitHub Copilot — Best for Coding Students
For programming students, a general chatbot is not always the most practical tool.
GitHub Copilot is designed around software development and can provide coding assistance inside supported development environments.
GitHub currently offers a free Copilot tier, while verified students can receive student access through GitHub Education. GitHub’s student documentation says verified students can access Copilot and its premium features through the education program.
Useful student tasks
Understanding unfamiliar code
Explaining error messages
Generating small code examples
Debugging
Refactoring
Learning programming concepts
Exploring APIs
Best practice
Don’t ask Copilot to complete an assignment and submit the result without understanding it.
Instead:
Write what you understand.
Ask for help with the difficult part.
Review the generated code.
Run tests.
Explain the code in your own words.
Check your course’s AI policy.
Best AI Tools by Student Task
Choosing by task is usually more useful than choosing by brand.
What you need
What to look for
Suitable tool types
Learn a difficult concept
Guided explanations
AI tutor
Prepare for an exam
Quizzes + adaptive practice
Study-focused AI
Study your own PDF
Source-grounded answers
AI notebook
Research a topic
Search + source discovery
Research AI
Improve an essay
Editing + feedback
Writing assistant
Memorize terminology
Active recall
Flashcard tool
Practice math
Worked explanations
Math-focused AI
Learn programming
Code + debugging support
Coding assistant
Build a presentation
Visual organization
Presentation AI
Organize a study plan
Planning + reminders
Productivity AI
The important question is not:
“Which AI tool is the most powerful?”
It is:
“Which tool fits the learning task I am doing right now?”
Best AI Tools for Studying
For ordinary studying, look for tools that can:
Explain concepts at different levels
Ask follow-up questions
Create practice questions
Review your notes
Identify weak areas
Help you practice without immediately revealing answers
ChatGPT’s Study Mode and Gemini’s study-notebook features are examples of the broader shift toward AI systems that are designed to support learning rather than simply provide a final response.
Best AI Tools for Homework Help
AI can be useful for homework when you use it as a tutor.
A productive workflow is:
Attempt the problem yourself.
Show the AI your attempt.
Ask it to identify the first mistake.
Request a hint.
Solve the next step yourself.
Ask for another hint if necessary.
Check the completed solution.
Explain the answer without looking at the AI response.
This approach is much more valuable than copying a generated solution.
If you are also comparing online study platforms, our Course Hero Review 2026 covers its study materials, textbook solutions, tutoring and AI-powered help in more detail.
Best AI Tools for Exam Preparation
AI can support exam preparation particularly well when it is used to create a feedback loop.
A practical exam workflow
Step 1: Upload or organize your permitted study material.
Step 2: Ask for the major concepts.
Step 3: Take a diagnostic quiz.
Step 4: Identify weak topics.
Step 5: Study those topics.
Step 6: Generate new questions.
Step 7: Take the quiz without assistance.
Step 8: Review mistakes.
Step 9: Repeat the weak areas.
Google’s current study-notebook approach uses a similar concept: an initial diagnostic quiz can identify knowledge gaps, followed by adaptive lessons and additional quizzes.
Best AI Tools for Research
AI can accelerate research, but students should separate finding information from verifying information.
Use AI to:
Discover terminology
Find possible research directions
Identify related concepts
Generate questions
Locate potential sources
Understand difficult papers
Then verify important information using the original source.
For academic writing, the original paper, book, government publication, university source, or recognized organization should take priority over an AI-generated summary.
Best AI Tools for Writing Essays
AI writing tools can help at different stages:
Before writing
Use AI to brainstorm possible questions or organize ideas.
During writing
Create your own argument and evidence.
After writing
Use an AI writing assistant to identify:
Grammar problems
Unclear sentences
Repetition
Weak transitions
Readability issues
Avoid asking an AI system to generate an entire essay and then submitting it as your own work unless your instructor explicitly permits that type of use.
Best AI Tools for Summarizing Notes and PDFs
AI summarization can save time when you have long course materials.
A good workflow is:
Original material → Summary → Check against original → Study questions → Self-test
Never assume a summary contains every important qualification or detail.
For important subjects, compare the summary with your original notes or textbook.
Best Free AI Tools for Students
“Free” is a more complicated term than it appears.
A tool may have:
A genuinely free plan
Limited daily usage
Limited models
Limited file uploads
A free trial
Education access
Student verification
Paid features that are optional
GitHub, for example, currently offers a free Copilot tier and also maintains a separate student benefit for verified students.
Google also offers different education and personal-account access models, and eligibility can depend on the account or institution.
Before recommending a tool to classmates, check its current pricing and eligibility because AI product plans can change quickly.
AI Tools for Different Types of Students
High school students
Prioritize:
Guided explanations
Practice questions
Flashcards
Study planning
Teacher-approved tools
Age restrictions and school policies matter particularly for younger students.
College students
Useful categories include:
Research
Writing feedback
Note summarization
Exam preparation
Presentations
Productivity
University and graduate students
Research-oriented capabilities become more important.
Consider:
Source discovery
Literature review workflows
Long-document analysis
Citation verification
Data analysis
Coding
STEM students
Useful categories include:
Math tutoring
Coding assistants
Scientific explanations
Problem-solving practice
Visualization
Humanities students
Useful categories include:
Research discovery
Writing feedback
Concept explanations
Source analysis
Argument development
How to Use AI for Studying Without Replacing Your Learning
The best student workflow is not:
Question → AI answer → Copy
A stronger workflow is:
Question → Attempt → Hint → Reason → Practice → Feedback → Recall
Example
Suppose you are studying a difficult chemistry topic.
Instead of:
“Explain everything about chemical equilibrium.”
try:
“Teach me chemical equilibrium as if I understand basic chemistry but keep getting equilibrium problems wrong. Ask me one question at a time and don’t reveal the answer until I attempt it.”
Then continue with:
Practice questions
Mistake analysis
Short quizzes
Flashcards
Retrieval practice
This forces you to participate in the learning process.
OpenAI’s Study Mode is explicitly designed around this type of guided interaction, including questions, step-by-step explanations, practice problems and knowledge checks.
Microsoft’s Study and Learn experience similarly emphasizes active learning, guided practice and interactive activities.
Is Using AI for School Cheating?
Not necessarily. It depends on how you use it and what your school, instructor, or assignment rules allow.
There is a meaningful difference between:
Learning support
Asking for an explanation
Getting a hint
Practicing questions
Creating revision material
Checking grammar
Brainstorming
Reviewing your own draft
Potentially problematic use
Submitting AI-generated work as your own
Generating an entire assignment when prohibited
Fabricating references
Using AI during a restricted exam
Hiding AI use when disclosure is required
Copying answers without understanding them
There is no universal academic-integrity rule that applies identically to every institution.
Check the specific policy for your class or university.
Common Mistakes Students Make With AI
1. Trusting every answer
AI can produce confident but incorrect information.
Verify important claims.
2. Copying instead of learning
If you never attempt the problem yourself, you may remember the AI’s answer but still struggle on the exam.
3. Inventing citations accidentally
Never assume an AI-generated citation exists.
Open the source and verify it.
4. Using outdated information
AI tools and academic information can change. Check dates when the topic requires current information.
5. Uploading sensitive information
Think before uploading:
Personal records
Private student information
Confidential documents
Unpublished research
Sensitive institutional material
Follow your school’s and the tool provider’s privacy requirements.
6. Using one tool for everything
Different tools have different strengths.
A coding assistant is not automatically the best research tool. A flashcard platform is not automatically the best essay editor.
7. Ignoring course rules
Even if a tool technically allows something, your instructor may not.
Your academic policy comes first.
How to Choose the Right AI Tool
Use this five-question decision process.
1. What am I trying to do?
Studying, research, writing, coding, revision, presentation design, or something else?
2. Do I need the AI to use my own materials?
If yes, look for a tool designed to work with uploaded notes, PDFs, readings, or course material.
3. Do I need sources?
If yes, prioritize tools and workflows that make source verification easier.
4. Do I need a tutor or an answer?
For learning, a guided tutor-style experience is often more useful than a system that simply gives the final answer.
5. What does my school allow?
This question should come before submitting anything generated or edited by AI.
A Practical AI Study Workflow for a Real Exam
Imagine you have a biology exam in three days.
Day 1: Diagnose
Collect your permitted notes and course materials.
Ask an AI study tool to help identify the major topics and create a diagnostic quiz.
Day 1: Find weak areas
Take the quiz without looking at the answers.
Mark the concepts you missed.
Day 2: Learn
Study the weak concepts individually.
Ask for:
simpler explanations
examples
analogies
practice problems
questions that test understanding
Day 2: Recall
Generate flashcards and short quizzes.
Answer them without looking at your notes.
Day 3: Simulate the exam
Ask for a mixed practice test.
Complete it under realistic conditions.
Then review your mistakes.
Final review
Focus on the concepts you still cannot explain without assistance.
That last step is important.
If you can only understand a concept while the AI is explaining it, you have not fully mastered it yet.
Key Takeaways
There is no single best AI tool for every student.
Choose AI based on the task rather than popularity.
Use AI tutors for explanations and guided practice.
Use source-grounded tools when studying your own materials.
Use research AI for discovery, but verify important sources yourself.
Use writing assistants to improve your own drafts.
Use flashcards and quizzes for active recall.
Coding students can benefit from dedicated coding assistants.
Check whether a tool is genuinely free or only has limited free access.
Never assume AI-generated information or citations are accurate.
Follow your school’s academic-integrity rules.
The most useful AI workflow makes the student do the thinking.
For more practical technology and educational resources, you can also explore HaroBuilder and its growing collection of guides.
Frequently Asked Questions
What are the best AI tools for students?
The best tool depends on the student’s task. General AI tutors such as ChatGPT can support explanations and practice, while tools such as Gemini’s study features, Gemini Notebook, Microsoft Study and Learn, research-oriented AI, writing assistants, flashcard platforms, presentation tools, and coding assistants address more specific needs.
Which AI tool is best for studying?
A learning-focused AI tool that can explain concepts, ask questions, create practice exercises, and help identify knowledge gaps is generally more useful for studying than an answer-only workflow. ChatGPT Study Mode and Gemini’s study-notebook features are examples of this learning-first approach.
What is the best free AI study tool?
There is no universal answer because free access varies by tool, account, country, age, institution, and feature. Check the provider’s current free plan or education offering before choosing a tool.
Can AI help with homework?
Yes. AI can help explain concepts, provide hints, create practice problems, and review mistakes. The most useful approach is to attempt the homework yourself first and use AI to support your reasoning rather than simply copying its answer.
Can AI help with exam preparation?
Yes. AI can help create practice questions, explain difficult topics, review notes, generate flashcards, and identify knowledge gaps. Google’s current study notebooks, for example, use diagnostic quizzes and adaptive lessons as part of an exam-preparation workflow.
Which AI tool is best for research?
The best choice depends on the research task. Research-oriented AI can help discover sources and understand a topic, but students should always open and verify the original source before using a claim in academic work.
What AI tools can summarize notes?
AI chatbots and source-grounded notebook tools can summarize notes, PDFs, readings, and other permitted course materials. Source-grounded workflows can be especially useful because the student can keep the summary connected to the material being studied.
Can AI generate flashcards?
Yes. Several AI study tools can create flashcard-style material from notes or topics. But generated cards should be checked for accuracy before being used for exam preparation.
Is using AI for school cheating?
Not automatically. The answer depends on the specific use and the rules of the class or institution. Asking for an explanation may be permitted while submitting an AI-generated assignment may be prohibited. Always follow the applicable academic-integrity policy.
Are AI tools safe for students?
Safety depends on the product, account type, age, institution, information being uploaded, and how the tool is used. Avoid uploading sensitive information unless you understand the applicable privacy protections and have permission to do so.
What is the best AI tool for college students?
College students may benefit from a combination of tools rather than one product: a general study assistant, a research tool, a note/PDF tool, a writing assistant, and specialized tools for subjects such as mathematics or programming.
Can students use AI without paying?
Many AI products provide some form of free access, while others have limited free tiers or student/education plans. Eligibility and features change, so students should check the provider’s current terms rather than relying on an old pricing list.
If you are researching AdaptiBar reviews before paying for bar-exam preparation, the biggest question in 2026 is no longer simply whether AdaptiBar has good MBE questions. You also need to know which exam format you are preparing for, what the current product includes, how much it costs, and whether you need a question bank or a complete bar-prep course.
AdaptiBar is primarily built around multiple-choice practice, adaptive studying, licensed NCBE questions, performance tracking, and explanations. Its current offerings also include a NextGen UBE MCQ Simulator, which makes the 2026 version of AdaptiBar different from older reviews you may find online.
Quick Answer: Is AdaptiBar Worth It?
AdaptiBar can be a useful bar-prep supplement when your main goal is focused multiple-choice practice, particularly if you want licensed NCBE questions, adaptive practice, and performance analytics.
The important limitation is that it should not automatically be treated as a complete replacement for every component of bar preparation. If you are preparing for the NextGen UBE, you also need to consider the exam’s broader skills and question formats. NCBE says most jurisdictions are transitioning from the legacy UBE to the NextGen UBE between July 2026 and July 2028.
So the better question is:
Does AdaptiBar match your exam format, study weaknesses, budget, and need for multiple-choice practice?
For many candidates, that is a more useful way to evaluate the product than simply asking whether it is “the best” bar-prep platform.
AdaptiBar Reviews 2026: What’s Changed?
Older AdaptiBar reviews can be useful for understanding the platform’s history, but they should not be treated as a current product specification.
The bar exam itself is changing.
The first operational administration of the NextGen UBE took place in July 2026 across 10 jurisdictions. NCBE says additional jurisdictions will begin administering the NextGen UBE in 2027 and 2028.
That matters because the legacy UBE and NextGen UBE are not identical.
The legacy UBE includes the:
Multistate Bar Examination (MBE)
Multistate Essay Examination (MEE)
Multistate Performance Test (MPT)
NCBE describes the NextGen UBE as a different assessment that focuses on foundational legal concepts and practical lawyering skills.
AdaptiBar now has a NextGen UBE MCQ Simulator designed around standalone multiple-choice questions. BARBRI’s current product information says that simulator includes 290 licensed NextGen MCQs, select-two and partial-credit formats, and eight foundational subjects.
That makes the exam date and jurisdiction an important part of any 2026 AdaptiBar review.
What Is AdaptiBar?
AdaptiBar is an online bar-exam preparation platform focused heavily on multiple-choice practice.
Its core product combines:
Licensed NCBE questions
Adaptive question delivery
Performance tracking
Practice exams
Answer explanations
Study analytics
Mobile access
Additional study resources
The current App Store listing describes AdaptiBar’s MCQ Simulator as combining licensed MBE questions from NCBE with adaptive technology that adjusts question presentation according to a user’s performance.
That makes AdaptiBar different from a traditional comprehensive course that attempts to cover every part of the bar exam through lectures, outlines, essays, practice questions, and other materials.
In practical terms, AdaptiBar is particularly relevant when your preparation strategy needs a strong multiple-choice practice component.
Who Is AdaptiBar Best For?
AdaptiBar may be particularly relevant for candidates who fall into one or more of these situations.
First-Time Bar Takers
A first-time candidate who already has a comprehensive study plan may use AdaptiBar for additional question practice and performance tracking.
The platform can help turn general studying into more targeted practice by showing performance across subjects and topics.
Repeat Bar Exam Takers
Retakers often have a different problem from first-time candidates.
They may already understand the general exam structure but need to determine:
Which subjects remain weak
Which question types cause problems
Whether timing is an issue
Whether accuracy falls under pressure
Which rules need additional review
AdaptiBar’s performance-oriented approach can be useful for this type of targeted preparation. BARBRI currently specifically identifies retakers focused on improving multiple-choice results as one audience for the MCQ Simulator.
Candidates Who Need More MCQ Practice
If your biggest weakness is multiple-choice performance, a dedicated question platform may be more useful than simply adding another general study resource.
Candidates Using a Comprehensive Bar Course
AdaptiBar can also function as a supplement rather than your entire study system.
The current AdaptiBar app description itself recommends using the platform as a supplement to a comprehensive bar review course.
AdaptiBar Features
Here is a practical overview of the major features to consider.
Feature
What It Provides
Why It Matters
Licensed NCBE questions
Officially licensed question content
Gives candidates exposure to authentic exam-style material
Adaptive practice
Questions adjust based on performance
Helps focus study on weaker areas
Performance analytics
Tracks results and progress
Helps identify problem subjects
Practice exams
Timed/customized practice
Useful for exam simulation
Answer explanations
Explains question reasoning
Supports learning from mistakes
Mobile access
Study through supported devices
Makes short practice sessions easier
NextGen MCQ Simulator
NextGen-specific MCQ practice
Relevant to transitioning jurisdictions
Flashcards/resources
Additional study support
Useful for review outside question sets
The current product information specifically emphasizes licensed multiple-choice questions and performance insights, while the NextGen version adds formats such as select-two and partial-credit questions.
Does AdaptiBar Use Real MBE Questions?
AdaptiBar uses licensed NCBE questions, but you should understand the distinction between licensed questions and questions written or modified by a prep provider.
Its current product information states that the platform provides licensed NCBE multiple-choice questions.
That distinction matters because a question bank can contain a mixture of:
Licensed NCBE questions
Provider-created questions
Modified questions
Simulated questions
These categories are not necessarily interchangeable.
AdaptiBar’s terms also explain that licensed materials can include modified questions and that NCBE does not endorse provider modifications.
For a bar candidate, the practical takeaway is simple:
Look at what portion of the product consists of licensed NCBE material and what portion is provider-created or modified content before comparing question banks.
How Does AdaptiBar Work?
The basic workflow is straightforward.
1. Start With Your Exam Format
First determine whether you are preparing for the legacy UBE/MBE or a NextGen UBE administration.
This step is especially important in 2026 because jurisdictions are transitioning at different times. NCBE maintains a current jurisdiction-by-jurisdiction schedule.
2. Build a Question Set
You can practice questions based on the subject or other available criteria.
3. Answer the Questions
Work through the questions under normal or timed conditions depending on your study stage.
4. Review the Explanation
Don’t stop after seeing whether you were right or wrong.
The explanation is where much of the learning happens.
Ask:
Why was my answer correct or incorrect?
What rule did I miss?
Why are the other choices wrong?
Was the problem legal knowledge, reading, timing, or reasoning?
5. Monitor Your Performance
Use performance information to identify weak areas.
6. Adjust Your Study Plan
If one subject consistently performs below the others, allocate more study time to that area rather than continuing to practice everything equally.
7. Repeat Under Timed Conditions
As the exam approaches, shift toward mixed and timed practice.
AdaptiBar Pricing: How Much Does It Cost?
Pricing is one area where older AdaptiBar reviews can become misleading.
Third-party pages may quote historical prices that are no longer current.
For example, UWorld’s current comparison page lists an older comparison price of $395 for AdaptiBar and notes a 1,608-question figure in its comparison table. That page was updated in August 2026, but its comparison table is explicitly labeled “2025,” so it should not automatically be treated as the current AdaptiBar price.
The safest approach is to check the current official product pricing immediately before purchase.
The App Store currently lists AdaptiBar as free to download with in-app purchases and shows a $599.99 MBE Simulator purchase and a $299.99 reenrollment option among the listed purchases.
Because pricing, promotions, access periods, and purchase channels can change, don’t rely on an old review quoting one fixed price.
What Should You Check Before Paying?
Look at:
Current total price
Access period
Exam date covered
Retaker pricing
Included question access
Licensed-question availability
Additional study resources
Automatic renewal terms, if applicable
Refund policy
Whether add-ons cost extra
For a high-cost bar-prep purchase, the checkout page should be your final pricing reference.
AdaptiBar’s NextGen UBE Option
This is one of the most important sections for a 2026 review.
AdaptiBar now offers a NextGen UBE MCQ Simulator.
BARBRI’s current product page says it includes:
290 licensed NextGen MCQs
Select-two questions
Partial-credit formats
Eight foundational subjects
Performance-focused practice
It is specifically designed for the NextGen UBE’s standalone multiple-choice component.
However, candidates should understand what that means.
The NextGen UBE is broader than a conventional multiple-choice-only preparation strategy.
So if your jurisdiction is administering the NextGen UBE, an MCQ simulator can address one part of preparation but should not automatically be treated as your complete preparation system.
Which States Use the NextGen UBE?
There is no single “2026 bar exam” experience across all UBE jurisdictions.
NCBE’s current adoption table shows different first-administration dates.
For example:
Connecticut — July 2026
Idaho — July 2026
Maryland — July 2026
Missouri — July 2026
Oregon — July 2026
Washington — July 2026
Arizona — July 2027
Iowa — July 2027
Kentucky — July 2027
Minnesota — July 2027
Illinois — February 2028
District of Columbia — February 2028
New York — July 2028
Texas — July 2028
Pennsylvania — July 2028
NCBE’s table is updated as jurisdictions finalize their policies, so candidates should verify their own jurisdiction rather than relying on a static article.
AdaptiBar Pros and Cons
Pros
Licensed NCBE questions
Access to licensed NCBE material is a major reason candidates consider the platform.
Adaptive practice
The platform’s adaptive approach can help direct practice toward areas where performance indicates a need for improvement.
Performance tracking
Analytics can be more useful than simply counting how many questions you answered.
Focused MBE preparation
Candidates who already have broad legal knowledge may value a dedicated multiple-choice tool.
Mobile access
The app allows candidates to practice outside a traditional desk-based study session. The App Store listing supports iPhone and iPad access.
NextGen option
The availability of a dedicated NextGen MCQ simulator makes current AdaptiBar more relevant to the changing exam environment.
Cons
It is not automatically a complete bar-prep solution
Candidates may need additional resources for essays, performance tasks, foundational instruction, or other exam components.
Pricing requires current verification
Older reviews contain outdated price figures, so candidates should check current pricing before purchasing.
The value depends on your study strategy
If you rarely use question banks, paying for a dedicated platform may make less sense than if multiple-choice practice is central to your plan.
NextGen candidates need broader preparation
The NextGen UBE measures skills beyond standalone MCQs.
Some user feedback is dated
A large portion of the publicly visible App Store written reviews are from earlier years, so they are useful for identifying recurring user experiences but should not be treated as a complete assessment of the current product.
What Do Users Say About AdaptiBar?
The current App Store listing shows 4.9 out of 5 from 2.2K ratings.
That is a useful signal, but it needs context.
The written reviews include positive comments about:
Licensed questions
Explanations
Adaptive practice
Mobile usability
Performance tracking
Some users also report limitations involving app behavior, interface preferences, or technical quirks.
Because many of the visible written reviews are from 2020–2024, they should be treated as historical user experiences, not proof that every feature works exactly the same way today.
A better review methodology is to combine:
Current product documentation + current pricing + current exam information + independent user feedback.
AdaptiBar vs UWorld
This is one of the most important comparisons for anyone researching MBE practice.
UWorld’s August 2026 comparison says its QBank includes more than 2,000 questions, including more than 1,350 licensed NCBE questions, while it describes AdaptiBar as having about 1,600 total questions, including roughly 1,400 licensed questions. These figures are claims presented by UWorld in its own comparison and should therefore be read in that context.
Factor
AdaptiBar
UWorld
Licensed question content
Yes
Yes
Adaptive practice
Yes
Performance-based tools
Performance analytics
Yes
Yes
Custom practice
Yes
Yes
Visual explanations
Available resources vary
Major emphasis
Flashcards
Available
Customizable tools
Mobile access
Yes
Yes
MBE focus
Strong
Strong
NextGen MCQ option
Yes
Verify current offering
Best fit
Focused/adaptive MCQ practice
QBank + visual learning approach
UWorld’s comparison emphasizes visual explanations, customizable flashcards, digital note-taking, and its own full-length assessment as differentiators.
Rather than asking which company is universally better, compare the learning method you actually prefer.
If you learn best by working through adaptive practice and targeted question sets, AdaptiBar may fit that workflow.
If visual explanations, customized notes, and integrated flashcards are especially important to you, UWorld’s current feature set may be more relevant.
AdaptiBar vs BARBRI
This comparison needs an important clarification.
BARBRI currently distributes and promotes AdaptiBar’s MCQ Simulator as a multiple-choice practice product. Its current page describes AdaptiBar as an option for candidates who want focused multiple-choice practice, including retakers and students building speed and accuracy.
That means the comparison should not simply be:
“Which brand is better?”
Instead ask:
Do you need a comprehensive course?
Do you mainly need MCQ practice?
Do you need essay preparation?
Do you need performance-task preparation?
Are you preparing for the legacy exam or NextGen UBE?
How much structure do you need?
A comprehensive course and a specialized question platform solve different problems.
AdaptiBar vs BarMax, Themis and Kaplan
These platforms should also be compared according to function rather than brand popularity.
AdaptiBar vs BarMax
Consider whether your priority is dedicated multiple-choice practice or broader course coverage.
AdaptiBar vs Themis
Consider whether you need a comprehensive preparation system or primarily want additional MCQ practice.
AdaptiBar vs Kaplan
Again, distinguish a full bar-prep curriculum from a specialized question-practice resource.
A common mistake is comparing all bar-prep products as if they were interchangeable.
They are not.
Is AdaptiBar Enough to Pass the Bar?
There is no responsible way to say that a particular prep platform is “enough” for every candidate.
Your needs depend on:
Exam format
Jurisdiction
Existing legal knowledge
First-time or repeat status
Strengths and weaknesses
Available study time
Essay preparation needs
Performance-task preparation
Multiple-choice performance
For the legacy UBE, the MBE is one component of the exam alongside essays and performance testing.
For the NextGen UBE, the exam also evaluates a broader set of lawyering skills.
So AdaptiBar should be evaluated according to the role you expect it to play in your preparation.
AdaptiBar for Retakers
AdaptiBar can be particularly relevant to repeat candidates who already know their basic preparation routine but need better multiple-choice diagnostics.
A useful retaker workflow is:
1. Start with a baseline
Take a meaningful set of questions under realistic conditions.
2. Identify weak subjects
Don’t only look at your overall percentage.
Look for patterns.
3. Separate knowledge problems from reasoning problems
You may know the law but still miss questions because you:
Misread the facts
Missed a key issue
Chose an attractive distractor
Ran out of time
Changed a correct answer unnecessarily
4. Review every missed question
Record the rule and the reason for your mistake.
5. Practice weak areas
Use targeted question sets before returning to mixed practice.
6. Add timed sessions
As your exam approaches, make your practice increasingly realistic.
How to Use AdaptiBar Effectively
Buying a question bank is only the first step.
Keep an error log
For each meaningful mistake, record:
Subject
Topic
Rule
Why your answer was wrong
Why the correct answer was right
What confused you
Review correct answers too
A correct answer can still be a lucky guess.
If you cannot explain why the correct choice is correct, you have not completely mastered the question.
Don’t chase percentages blindly
A higher percentage is useful, but it does not automatically mean you are ready for exam day.
Look for improvement in:
Accuracy
Timing
Consistency
Weak-subject performance
Mixed-question performance
Practice under realistic conditions
Untimed practice is useful early.
Timed mixed sets become increasingly important as the exam gets closer.
Use your analytics to change your study plan
Analytics are useful only if they change what you do next.
Who Should Consider AdaptiBar?
AdaptiBar may be worth considering if you:
Want dedicated multiple-choice practice
Want licensed NCBE questions
Need performance analytics
Prefer adaptive study
Are a repeat candidate
Already have a comprehensive course
Need additional MBE practice
Want mobile practice options
You may need additional resources if you:
Need comprehensive essay instruction
Need extensive performance-task preparation
Need foundational legal instruction
Need a full NextGen curriculum
Prefer a highly visual learning platform
Want one platform covering every component of your exam
The right choice depends on the gap you are trying to fill.
AdaptiBar Alternatives
Instead of treating one platform as universally superior, group alternatives according to the problem they solve.
Your Main Need
Resource Type to Consider
Licensed MBE questions
Dedicated MBE question bank
Complete bar preparation
Comprehensive bar course
Visual explanations
Visual-first QBank
Memorization
Flashcards
Repeat-taker diagnostics
Analytics-focused question platform
NextGen UBE
NextGen-specific preparation resources
Essay preparation
MEE-focused resources
Performance tasks
MPT/NextGen skills resources
This approach makes a comparison more useful because the “best” resource depends heavily on the candidate’s actual preparation gap.
Common Mistakes When Choosing AdaptiBar
Mistake 1: Using an old review for current pricing
Prices and product packages change.
Always check current pricing before purchase.
Mistake 2: Ignoring your jurisdiction’s exam format
In 2026, this is particularly important.
NCBE’s current jurisdiction table shows different NextGen UBE implementation dates, ranging from July 2026 through July 2028 and beyond for jurisdictions still finalizing policies.
Mistake 3: Assuming a QBank replaces the whole exam
Multiple-choice practice is only one part of a broader preparation strategy.
Mistake 4: Counting questions instead of reviewing them
Completing thousands of questions is not automatically useful if you rush through explanations.
Mistake 5: Practicing only your strongest subject
Your strongest area is not necessarily where additional study time produces the biggest improvement.
Frequently Asked Questions About AdaptiBar
Is AdaptiBar worth it in 2026?
AdaptiBar can be useful for candidates who need focused multiple-choice practice, licensed NCBE questions, adaptive practice, and performance tracking. Its value depends on your exam format and whether you need a question bank, a supplement, or a broader preparation system.
How much does AdaptiBar cost?
Current pricing can vary by product and purchase channel. The current App Store listing shows a $599.99 MBE Simulator purchase and a $299.99 reenrollment option, but candidates should verify the price and package on the official purchase page before paying.
Does AdaptiBar use real NCBE questions?
Yes. AdaptiBar’s current product information states that it provides licensed NCBE multiple-choice questions. The platform can also contain provider-created or modified material, so candidates should understand the distinction between licensed and simulated content.
How many questions does AdaptiBar have?
Question counts depend on the specific AdaptiBar product and exam format. BARBRI currently lists 290 licensed NextGen MCQs for its NextGen UBE MCQ Simulator. Older MBE question counts appearing in third-party reviews may not represent the current product.
Is AdaptiBar good for MBE preparation?
Its product is specifically centered on multiple-choice practice and includes licensed MBE questions and adaptive performance tools, making MBE preparation a core use case.
Is AdaptiBar good for retakers?
It can be useful for retakers who want to diagnose multiple-choice weaknesses, increase question volume, improve timing, and target specific subjects. BARBRI explicitly identifies retakers as one audience for the current MCQ Simulator.
Is AdaptiBar enough to pass the bar?
No preparation platform should be treated as a guaranteed pass solution. Whether it provides enough preparation depends on your jurisdiction, exam format, strengths, weaknesses, and whether you also need essay, performance-task, or broader instructional resources.
Is AdaptiBar better than UWorld?
There is no single answer for every candidate. AdaptiBar emphasizes adaptive practice and licensed questions, while UWorld’s current comparison emphasizes visual explanations, customizable study tools, and its own question bank. Compare the platforms according to your preferred learning style and preparation needs.
Does AdaptiBar work for the NextGen UBE?
AdaptiBar currently offers a NextGen UBE MCQ Simulator with 290 licensed NextGen MCQs, select-two and partial-credit formats, and eight foundational subjects. However, the NextGen UBE covers broader lawyering skills, so an MCQ simulator should not automatically be treated as complete NextGen preparation.
Does AdaptiBar have a free trial?
The current App Store listing says AdaptiBar offers a free Test Drive, while full-program app access is associated with the full program. Check the current official offering before signing up because trial terms can change.
Does AdaptiBar have a mobile app?
Yes. AdaptiBar has an iPhone and iPad app, and the current App Store listing identifies the developer as AdaptiGroup LLC.
What does AdaptiBar include?
Depending on the product, AdaptiBar provides licensed questions, adaptive practice, performance analytics, explanations, practice functionality, and additional study resources. The NextGen MCQ Simulator has a separate feature set focused on NextGen multiple-choice formats.
Final Takeaways: AdaptiBar Reviews 2026
AdaptiBar remains primarily a multiple-choice-focused bar-preparation resource, with licensed NCBE content, adaptive practice, performance tracking, and mobile access among its major features.
The biggest consideration in 2026 is the transition from the legacy UBE to the NextGen UBE.
If your jurisdiction is still administering the legacy MBE, evaluate AdaptiBar primarily around its MBE question bank, analytics, adaptive practice, and study workflow.
If your jurisdiction is administering the NextGen UBE, look specifically at the NextGen MCQ Simulator and then consider what additional resources you need for the exam’s broader lawyering skills. NCBE confirms that jurisdictions are transitioning on different schedules, so checking your jurisdiction’s current status is essential.
For more practical guides and research-based resources, explore HaroBuilder.
The most sensible way to evaluate AdaptiBar is not simply to ask, “Is it good?”
Ask:
Does it solve the preparation problem I currently have?
That question gives you a much clearer basis for deciding whether the subscription fits your bar-exam strategy.