
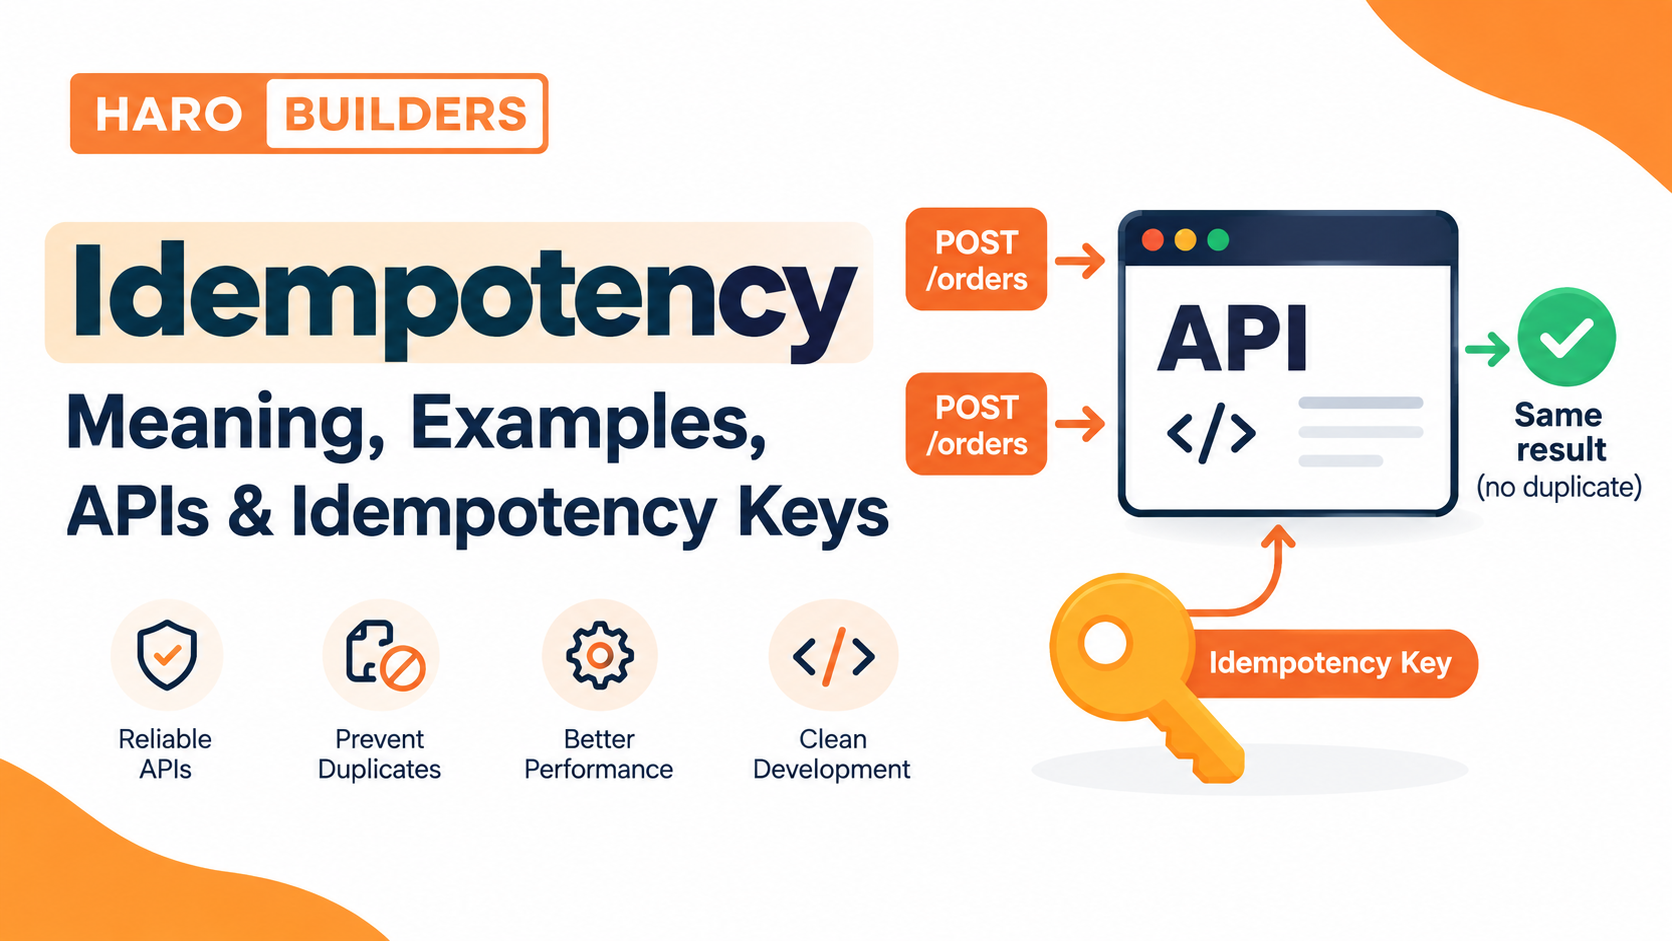
Imagine a customer clicks Pay on an online checkout. The payment reaches the server, but the customer’s connection times out before the response comes back. The customer tries again.
Without proper protection, the system could process the payment twice.
This is where idempotency matters.
Idempotency allows a system to safely receive the same logical request more than once without producing the same unintended side effect repeatedly. It is particularly important for APIs, payment systems, distributed applications, webhooks, and any software that needs to retry requests after network or server failures.
In simple terms:
Idempotency means that repeating the same operation produces the same intended effect as performing it once.
HTTP defines idempotency in terms of the intended effect of repeated requests on server state. An idempotent request can still return different responses on subsequent attempts; for example, deleting an already-deleted resource may return a different status code the second time.
Quick Answer: What Is Idempotency?
Idempotency is a property of an operation that allows the same operation to be performed multiple times while producing the same intended result as performing it once.
For example, setting an account’s status to ACTIVE multiple times still leaves the account ACTIVE. By contrast, an operation that adds $10 to an account balance each time is not idempotent because repeating it changes the result repeatedly.
Idempotency is especially valuable when clients retry requests because of timeouts, lost connections, or temporary failures.
What Does “Idempotent” Mean?
Idempotent describes an operation that can be repeated without changing its intended outcome beyond the first successful application.
The distinction is simple:
- Idempotency = the property or concept.
- Idempotent = describes an operation that has that property.
- Idempotent operation = an operation that can safely be repeated.
- Idempotency key = an identifier used by an API to recognize repeated attempts at the same logical operation.
A useful way to think about it is:
One logical operation → multiple delivery attempts → one intended effect
This is different from saying that the server literally executes the underlying code only once. An implementation can receive or process multiple attempts while still ensuring that the externally visible business effect happens only once.
A Simple Idempotency Example
Consider two operations.
Operation A: Set a user’s status
Set status = ACTIVE
If the request is received once:
ACTIVE
If it is received five times:
ACTIVE
The intended final state is the same.
That makes the operation idempotent.
Operation B: Increase a balance
Add $10 to balance
Starting balance:
$100
One request:
$110
Two requests:
$120
Three requests:
$130
Repeating the operation creates another effect each time.
That operation is not idempotent.
The important question is therefore not:
“Did the request run more than once?”
The better question is:
“Does repeating the same logical operation create another unintended effect?”
Idempotent vs. Non-Idempotent Operations
| Operation | Usually idempotent? | Why |
|---|---|---|
Set user status to ACTIVE | Yes | Repeating it leaves the same state |
| Replace a resource with the same representation | Yes | Repeated replacement has the same intended effect |
| Delete a resource | Yes | Repeated deletion does not keep removing additional copies of the same resource |
| Read a resource | Yes | Repeating the request does not intentionally change the resource |
| Increment a counter | No | Every request increases the value |
| Add a new order | Not inherently | Repeating it can create multiple orders |
| Charge a payment | Not inherently | Repeating it can create multiple charges |
| Append an item to a list | No | Every request can add another item |
The exact behavior depends on the operation’s semantics and implementation. HTTP’s definition focuses on the intended effect of repeated requests rather than requiring identical responses.
How Does Idempotency Work?
A typical idempotent API follows a process like this:
Client
   ↓
Send request + idempotency key
   ↓
Server checks the key
   ↓
Has this operation already been processed?
   ├── No → Process operation
   │        ↓
   │     Store result
   │        ↓
   │     Return response
   │
   └── Yes → Return stored result
The critical idea is that the server needs a reliable way to recognize that two requests represent the same logical operation.
For example:
Idempotency-Key: order-8f92c1
The client sends the request.
If the response is lost, the client sends the same logical request again using the same key.
The server can recognize:
order-8f92c1
as the same operation instead of treating the retry as an entirely new transaction.
Why Is Idempotency Important?
Idempotency becomes important when a request can be delivered more than once.
That can happen because of:
- network interruptions
- client timeouts
- server timeouts
- proxy failures
- connection resets
- user double-clicks
- automatic retry mechanisms
- message redelivery
- worker restarts
- load-balancer behavior
- distributed-system failures
A client may not know whether a request failed before processing or after processing but before the response reached the client.
That distinction creates a dangerous situation.
Example
Suppose a customer submits:
POST /payments
The server receives it and successfully charges the card.
Before the response reaches the customer, the network connection fails.
The customer sees:
Request failed
But the payment actually succeeded.
If the client blindly sends another payment request, the system could create a duplicate charge unless the API has an appropriate mechanism for recognizing the repeated logical operation.
This is one reason idempotency is closely associated with reliable APIs and retry handling.
Idempotency in APIs
API requests commonly travel through several components:
Client
   ↓
Internet
   ↓
Load Balancer
   ↓
API Server
   ↓
Application
   ↓
Database
   ↓
External Service
Any part of that chain can fail or become unavailable.
A client may therefore retry a request without knowing whether the original operation completed.
For readers who want a broader explanation of how clients, servers, requests, responses, network dependency, and server availability fit together, HaroBuilder’s guide to client-server architecture provides useful background.
A robust API should distinguish between:
A new logical operation
and
another delivery attempt for an existing logical operation.
An idempotency key is one common way to make that distinction.
Which HTTP Methods Are Idempotent?
HTTP semantics classify several request methods as idempotent.
| HTTP Method | Idempotent? | General reason |
|---|---|---|
| GET | Yes | Retrieves a resource |
| HEAD | Yes | Retrieves response metadata without a response body |
| OPTIONS | Yes | Requests communication options |
| PUT | Yes | Replaces the target representation with the supplied representation |
| DELETE | Yes | Repeated deletion has the same intended resource-state effect |
| POST | Not inherently | May create a new resource or trigger another side effect |
| PATCH | Not inherently | Applies a partial modification that may produce a new effect when repeated |
MDN documents GET, HEAD, PUT, DELETE, and OPTIONS as idempotent, while POST and PATCH are not guaranteed to be idempotent.
Does an idempotent HTTP method have to return the same response?
No.
Consider:
DELETE /users/123
The first request might return:
200 OK
A later identical request might return:
404 Not Found
The response changed, but the intended server-state effect can still satisfy the HTTP definition of idempotency.
This is an important distinction because idempotency is about the intended effect, not identical responses.
What Is an Idempotency Key?
An idempotency key is a unique identifier attached to a request so the server can recognize repeated attempts at the same logical operation.
A simplified request might look like:
POST /api/orders
Content-Type: application/json
Idempotency-Key: 7d2f8c41-4f7c-4e35-a912-91c42a8b31d7
{
  "product_id": "P100",
  "quantity": 1
}
If the client does not receive a response, it can retry the request with the same idempotency key.
The key tells the server:
“This is another attempt to deliver the same logical operation.”
The Idempotency-Key header is currently documented by MDN as a mechanism that can be used to make POST and PATCH requests idempotent when supported by the server. MDN also notes that the header itself is not currently a standardized HTTP header and that server-specific requirements should be documented.
How Should an Idempotency Key Be Used?
A useful rule is:
New logical operation
        ↓
New idempotency key

Retry of same logical operation
        ↓
Same idempotency key
For example:
First attempt
Key: payment-abc123
Amount: $50
Retry
Key: payment-abc123
Amount: $50
The same key tells the server that both requests belong to the same logical operation.
But this is different:
Key: payment-xyz789
Amount: $50
That should normally represent a new operation.
What If the Same Key Is Used With Different Data?
This is an important edge case.
Suppose the first request is:
Idempotency-Key: abc123

{
  "amount": 50
}
Then a later request uses:
Idempotency-Key: abc123

{
  "amount": 500
}
The application now has a problem.
Is this:
- a retry?
- a modified request?
- an accidental key reuse?
- a potentially dangerous client bug?
A robust implementation should define what happens.
One approach is to store a request fingerprint or relevant request parameters alongside the idempotency key. MDN’s current documentation describes this pattern and notes that a server can reject reuse of the same key with a different request fingerprint.
How to Implement Idempotency
A production implementation generally needs more than simply adding an HTTP header.
Step 1: Identify operations that need protection
Start with operations where duplicate execution could cause harm.
Examples include:
- creating an order
- charging a payment
- creating a subscription
- sending a message
- provisioning a resource
- submitting a job
- processing a webhook
- creating a database record
Not every read operation needs an application-level idempotency key.
Step 2: Generate a unique key
The client generates a key for each new logical operation.
For example:
3f2504e0-4f89-41d3-9a0c-0305e82c3301
The exact format depends on the API.
The critical requirement is that the key should distinguish one logical operation from another.
Step 3: Send the key with the request
For example:
POST /api/orders
Idempotency-Key: 3f2504e0-4f89-41d3-9a0c-0305e82c3301
The client should reuse that key when retrying the same logical operation.
Step 4: Check whether the key already exists
The server checks its durable idempotency store.
Conceptually:
Does key X already exist?
If no:
Reserve key
Process operation
Store result
Return result
If yes:
Do not create the same side effect again
Return the previously stored result or defined duplicate response
Step 5: Make the check and reservation safe
This is where many simplistic implementations fail.
Imagine two identical requests arrive almost simultaneously:
Request A → check key → doesn't exist
Request B → check key → doesn't exist
Both could continue.
That can produce duplicate work.
The check and reservation therefore need appropriate concurrency control, such as a database uniqueness constraint, transaction, atomic insert, lock, or another mechanism appropriate to the architecture.
Step 6: Store enough information to handle retries
Depending on the application, the server may need to store:
- idempotency key
- operation status
- request fingerprint
- response status
- response body
- resource ID
- timestamps
- error state
- expiration information
The exact storage strategy depends on the business operation.
Step 7: Define expiration
Idempotency records do not necessarily need to remain forever.
But expiration needs to be chosen carefully.
If the key disappears too quickly and the client retries later, the server might treat the retry as a new operation.
Therefore, the retention period should reflect:
- maximum expected retry period
- client behavior
- queue delays
- network conditions
- business risk
- operation lifetime
The server should document its key-expiration behavior when clients depend on it.
A Practical Idempotency-Key Example
Imagine an order API.
First request
POST /api/orders
Idempotency-Key: order-12345
{
  "customer_id": 72,
  "product_id": "LAPTOP-01",
  "quantity": 1
}
The server creates:
Order #9001
and returns:
{
  "order_id": "9001",
  "status": "created"
}
Now suppose the client never receives that response.
It retries:
POST /api/orders
Idempotency-Key: order-12345
The server recognizes the key.
Instead of creating:
Order #9002
it can return the result associated with the original operation according to the API’s defined behavior.
This is the practical value of idempotency.
Idempotency and Concurrent Requests
Retries are not the only source of duplicates.
Two requests can arrive at nearly the same time.
For example:
Request A ───────→ Server
Request B ───────→ Server
Both might use:
Idempotency-Key: abc123
A naive implementation might perform:
Check key
    ↓
Not found
    ↓
Process request
for both requests before either one has recorded the key.
That creates a race condition.
A safer design makes the creation of the idempotency record atomic.
For example:
Try to create unique key
        ↓
Success?
   ├── Yes → Process operation
   └── No  → Existing operation → handle as duplicate
This is one reason database constraints and transactions can be important parts of an idempotency design.
Idempotency in Payment Processing
Payments are one of the clearest examples.
Suppose:
Customer → Pay $100
The payment provider receives the request.
The charge succeeds.
But the response is lost.
The customer retries.
Without a way to identify the original logical operation, the second request could potentially create another charge.
With an idempotency mechanism:
Payment attempt
       ↓
Unique operation key
       ↓
Payment processed
       ↓
Result stored
       ↓
Retry with same key
       ↓
Original result recognized
This doesn’t remove every payment-system failure mode, but it gives the application a way to make repeated delivery safe for the operation it controls.
Idempotency in Webhooks
Webhooks create another common duplicate-processing problem.
A provider may send an event such as:
payment.completed
event_id = evt_123
Your application processes it.
Then the provider sends the same event again.
A webhook consumer can maintain a record of processed event identifiers:
evt_123 → processed
When the same event arrives again:
evt_123 → already processed
The application can avoid repeating the business side effect.
This pattern is especially useful when the delivery system uses retry behavior or otherwise permits duplicate delivery.
Idempotency in Microservices
Consider a simple architecture:
Order Service
      ↓
Payment Service
      ↓
Inventory Service
      ↓
Shipping Service
A failure can occur after one service has completed its work but before the caller receives confirmation.
That makes retries more complicated.
For example:
Order Service
     ↓
Payment Service
     ↓
Payment succeeds
     X
Response lost
The Order Service may retry.
If the Payment Service treats the retry as a completely new operation, the same payment could be attempted again.
A useful distributed-system design therefore carries a stable operation identity through the relevant processing chain.
AWS guidance similarly recommends propagating idempotency tokens through downstream services so duplicate messages do not create repeated side effects throughout a distributed workflow.
For readers who want to understand the broader request/response relationship and service dependencies first, HaroBuilder’s client-server architecture guide is a useful supporting resource.
Idempotency in Databases
Database design can also help enforce idempotent behavior.
Useful mechanisms can include:
- unique constraints
- transactions
- upserts
- conditional writes
- atomic inserts
- state transitions
- processed-event tables
For example, suppose each payment has a unique external transaction ID.
The database can enforce:
transaction_id = unique
If the application receives the same transaction again, the uniqueness rule can prevent a second record from being created.
However, a unique database field alone is not always enough.
The complete operation may involve:
Database
+
Payment provider
+
Email service
+
Inventory system
The application still needs to reason about external side effects.
Idempotency vs. Retry
These concepts are related, but they are not the same.
| Concept | Meaning |
|---|---|
| Retry | Attempt the request again |
| Idempotency | Make repeated attempts have the same intended effect |
| Idempotency key | Identifier used to recognize repeated logical requests |
| Timeout | A condition where the client stops waiting for a response |
A retry mechanism without idempotency can be dangerous.
For example:
Request
  ↓
Timeout
  ↓
Retry
  ↓
Duplicate side effect
With idempotency:
Request
  ↓
Timeout
  ↓
Retry with same key
  ↓
Recognize existing operation
  ↓
Avoid duplicate effect
So:
Retry is the action. Idempotency is a property that makes repeated execution safe.
Idempotency vs. Exactly-Once Processing
These terms are often confused.
Idempotency does not automatically prove that the underlying code physically executed only once.
Instead, the goal is generally to ensure that repeated attempts produce the same intended business effect as one successful operation.
Consider:
Request A
   ↓
Operation starts
   ↓
Response lost
   ↓
Request B
Both requests may reach the system.
An idempotent design can recognize that both correspond to one logical operation and prevent a duplicate business effect.
Distributed systems make true exactly-once execution difficult because failures can occur between processing steps and acknowledgments. AWS discusses the distinction between at-most-once, at-least-once and exactly-once behavior in its reliability guidance.
A useful mental model is:
At most once
→ Don't retry aggressively

At least once
→ Retry until success is confirmed

Idempotent processing
→ Repeated attempts don't create repeated unintended effects

Exactly once
→ Stronger execution/processing guarantee that is difficult to achieve end-to-end
Do not use “idempotent” and “exactly once” as interchangeable terms.
Idempotency vs. Uniqueness
Uniqueness and idempotency solve different problems.
Uniqueness
Answers:
“Can two records have the same identifier?”
Example:
email must be unique
Idempotency
Answers:
“What happens if this logical operation is delivered more than once?”
For example:
Order request
+
same operation key
+
retry
=
same intended order effect
A unique database field can support an idempotent design, but uniqueness alone does not make an entire workflow idempotent.
Common Idempotency Mistakes
1. Generating a new key for every retry
If every retry gets a new key, the server may interpret every attempt as a new operation.
Correct:
New operation → Key A
Retry → Key A
Retry → Key A
Not:
New operation → Key A
Retry → Key B
Retry → Key C
2. Storing keys only in application memory
In a multi-server environment, one request might reach Server A while its retry reaches Server B.
If the idempotency state exists only in Server A’s memory, Server B may not know about the previous request.
The state therefore needs an appropriate shared or durable mechanism.
3. Ignoring concurrent requests
A simple:
SELECT
then
INSERT
pattern can have a race condition if two requests execute it simultaneously.
The reservation step should use an appropriate atomic mechanism.
4. Accepting different payloads under the same key
A key should not silently represent multiple unrelated operations.
The API should define how it handles:
same key + same request
versus:
same key + different request
Request fingerprinting or validation can help.
5. Expiring keys too early
If a retry arrives after the record has expired, the server may process it as a new operation.
Retention should therefore match realistic retry and recovery behavior.
6. Protecting only the first database write
Suppose an operation performs:
Create order
↓
Charge payment
↓
Send email
Preventing duplicate order records does not automatically guarantee that the payment or email side effects are protected.
The entire workflow needs appropriate failure handling.
7. Assuming an idempotent HTTP method solves everything
Using PUT or DELETE does not automatically make every application endpoint safe.
The application still needs to implement the intended semantics correctly. MDN explicitly notes that real-world servers are responsible for adhering to HTTP method semantics.
Idempotency Best Practices
A practical production checklist:
API design
- Define which operations require idempotency.
- Document retry behavior.
- Document key requirements.
- Define key expiration.
- Decide how duplicate requests are handled.
- Decide how conflicting payloads are handled.
Storage
- Use an appropriate durable store.
- Protect the key with a uniqueness mechanism.
- Store enough information to identify the operation.
- Consider the required retention period.
Concurrency
- Make key reservation atomic.
- Handle simultaneous requests.
- Define an in-progress state.
- Avoid check-then-act race conditions.
Error handling
- Distinguish retryable failures from permanent failures.
- Define what happens when processing is still underway.
- Avoid creating a new logical operation during a retry.
Distributed systems
- Propagate operation identity when necessary.
- Make downstream operations retry-safe.
- Track duplicate messages.
- Consider external side effects.
Security
- Avoid putting sensitive information directly into idempotency keys.
- Validate key length and format.
- Consider abuse and storage limits.
- Do not treat an idempotency key as an authentication credential.
How to Test Idempotency
Don’t test only the happy path.
A useful test plan includes:
| Test | Expected behavior |
|---|---|
| First request | Operation succeeds |
| Exact retry | No unintended duplicate effect |
| Retry after timeout | Existing logical operation recognized |
| Two concurrent requests | Only intended effect occurs |
| Same key, same payload | Treated as same operation |
| Same key, different payload | Defined conflict/error behavior |
| Server restart | Idempotency state remains available if required |
| Database failure | No inconsistent duplicate state |
| Downstream failure | Recovery behavior is defined |
| Expired key | Documented behavior occurs |
| Duplicate webhook | Event does not create another unintended effect |
Testing concurrency is particularly important because an implementation can appear correct during sequential tests while still failing when two identical requests arrive simultaneously.
A Practical Idempotency Checklist
Before calling an API operation idempotent, ask:
- Can the request be safely retried?
- How does the server identify the logical operation?
- Is an idempotency key required?
- Is the key reused for retries?
- Is key storage durable enough for the use case?
- Is key creation atomic?
- Are concurrent requests handled?
- Are different payloads under the same key rejected or handled?
- How long are keys retained?
- What happens if processing is still in progress?
- Are downstream operations also protected?
- Are external side effects considered?
- Are duplicate webhooks/messages handled?
- Has the failure path been tested?
If several of these questions have no clear answer, the operation may not yet have a robust idempotency design.
Frequently Asked Questions About Idempotency
What is idempotency in simple words?
Idempotency means repeating the same logical operation does not create another unintended effect. For example, setting a user’s status to ACTIVE multiple times still leaves the user ACTIVE.
What does idempotent mean in programming?
An idempotent operation can be executed repeatedly while preserving the same intended outcome. The operation’s implementation determines whether it actually behaves idempotently.
Why is idempotency important in APIs?
APIs can experience timeouts, connection failures, retries, and duplicate requests. Idempotency helps prevent those repeated attempts from creating unintended duplicate effects.
What is an idempotency key?
An idempotency key is a unique identifier associated with a logical request. A client normally reuses the same key when retrying that operation so the server can recognize the repeated attempt.
Which HTTP methods are idempotent?
HTTP defines GET, HEAD, PUT, DELETE, and OPTIONS as idempotent. POST and PATCH are not guaranteed to be idempotent by HTTP semantics.
Is POST idempotent?
Not inherently. Repeating a POST request can create multiple resources or side effects. However, an application can design a POST endpoint to support idempotency, for example by using an idempotency key.
Is PATCH idempotent?
PATCH is not guaranteed to be idempotent by HTTP semantics. Whether a particular PATCH operation behaves idempotently depends on how the endpoint is designed and implemented.
Does idempotency mean the request runs only once?
No. Idempotency concerns the intended effect of repeated operations. Multiple attempts may reach or execute parts of a system while the application prevents duplicate business effects.
Is idempotency the same as exactly-once processing?
No. Idempotency can make repeated attempts produce one intended effect, but that does not automatically guarantee that every underlying processing step executes exactly once.
How does idempotency prevent duplicate transactions?
A system can associate a unique operation key with the transaction, store its processing state or result, and recognize subsequent attempts using the same key. The exact implementation depends on the transaction and architecture.
Key Takeaways
- Idempotency means repeated execution has the same intended effect as one execution.
- It is particularly valuable when requests can be retried.
- Idempotency keys help APIs recognize repeated attempts at the same logical operation.
GET,HEAD,PUT,DELETE, andOPTIONSare defined as idempotent HTTP methods.POSTandPATCHare not inherently idempotent.- Idempotency is different from retry, uniqueness, and exactly-once processing.
- Concurrent requests require careful implementation.
- Payments, orders, webhooks, and distributed systems are common use cases.
- Durable state, atomic operations, request validation, and appropriate testing are important for robust implementations.
Final Thoughts
Idempotency is one of those software concepts that becomes much easier once you connect it to a real failure scenario.
A timeout does not necessarily mean an operation failed. A request may have reached the server and completed even though the client never received the response. If the client retries without a way to identify the original logical operation, duplicate side effects can occur.
A well-designed idempotent system treats retries as part of normal failure handling rather than as exceptional events.
For more practical technology, SEO, and digital resources, explore HaroBuilder’s guides and resources.
Authoritative References
- MDN — HTTP idempotency and HTTP methods
- MDN —
Idempotency-Keyheader - AWS Well-Architected Framework — making mutating operations idempotent
These references provide the underlying HTTP and distributed-system concepts used throughout this guide.
💬 Comments 0
No comments yet. Be the first to share your thoughts! 💬
✍️ Leave a Comment